MaHui | Moonshot AI Releases Kimi K3, World's First Open-Source 3-Trillion-Parameter Model
This is the most capable model Moonshot AI has released to date.
("To aim for the farthest, one must venture into the hardest. Launch with courage, sustain with focus, and achieve through strength.")
In the early hours this morning, MaHui member Moonshot AI officially launched Kimi K3, its most capable model to date.
Kimi K3 is a 2.8 trillion parameter model built on the KDA hybrid linear attention mechanism (Kimi Delta Attention) and Attention Residuals technology. It features native visual understanding and a 1 million token context window. It is the world's first open-source model at the 3-trillion scale, designed for frontier intelligence scenarios including long-horizon programming, knowledge work, and reasoning.
While Kimi K3's overall performance still trails the strongest closed-source models Claude Fable 5 and GPT-5.6 Sol, it demonstrated frontier-level capabilities across our full evaluation suite and consistently outperformed all other models.
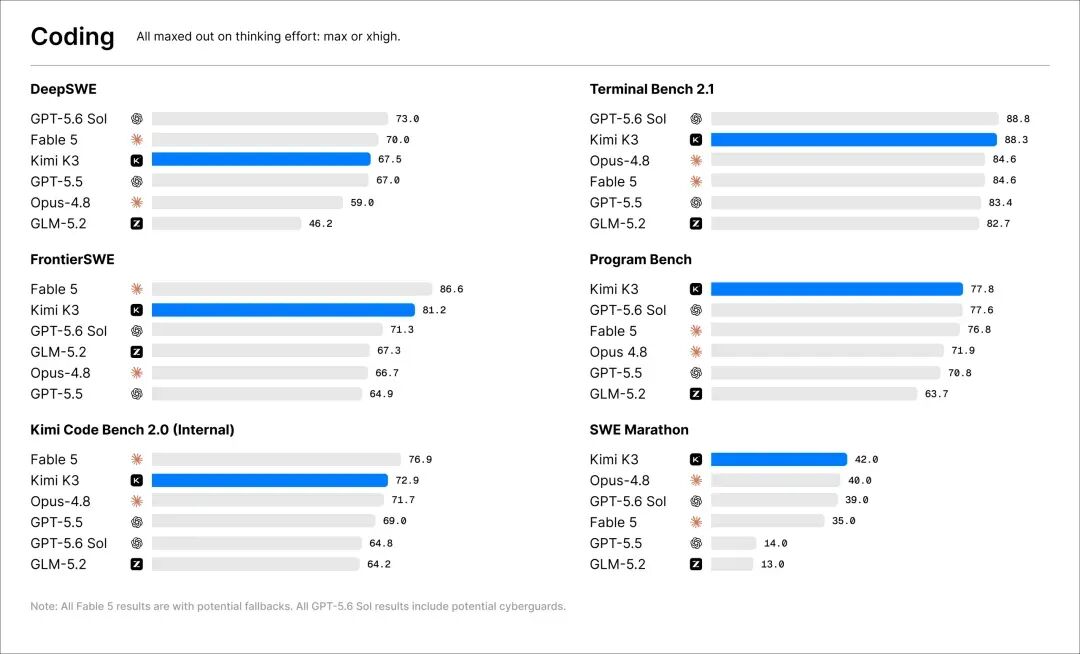
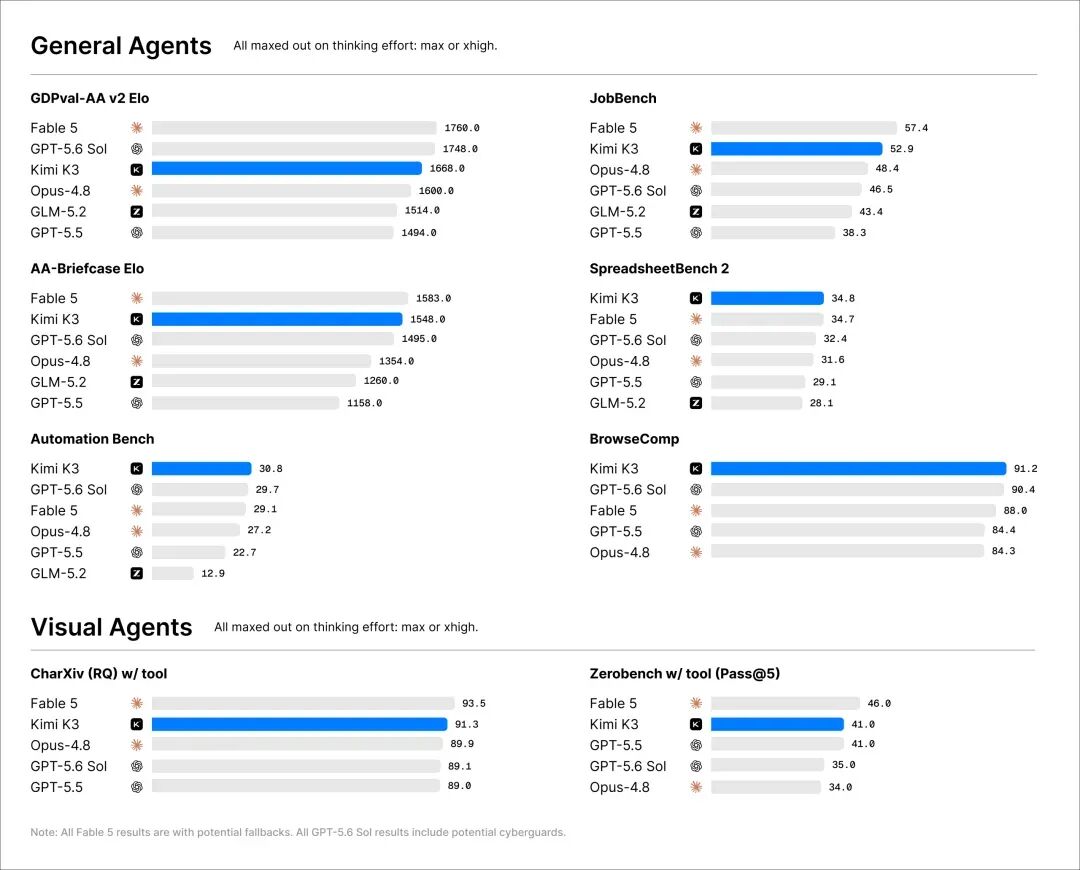
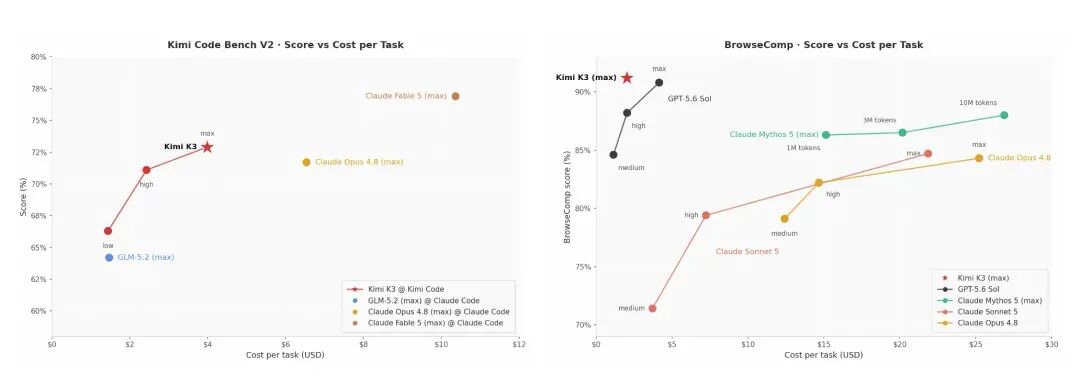
The launch of Kimi K3 is just the beginning. We will continue to unlock the model's potential and steadily improve its performance on real-world tasks.
Starting today, Kimi K3 is available through kimi.com, the latest Kimi mobile app, the latest Kimi Work desktop client, Kimi Code, and the Kimi API. The current default thinking intensity is max (extreme); low and high modes will be added in a future update.
We are currently working closely with inference partners and open-source maintainers to align on technical details and ensure reliable deployment across the ecosystem. Full model weights will be released by July 27, 2026. Additional details on architecture, training, and evaluation will be published alongside the Kimi K3 technical report.
A 3-Trillion-Scale Open-Source Model
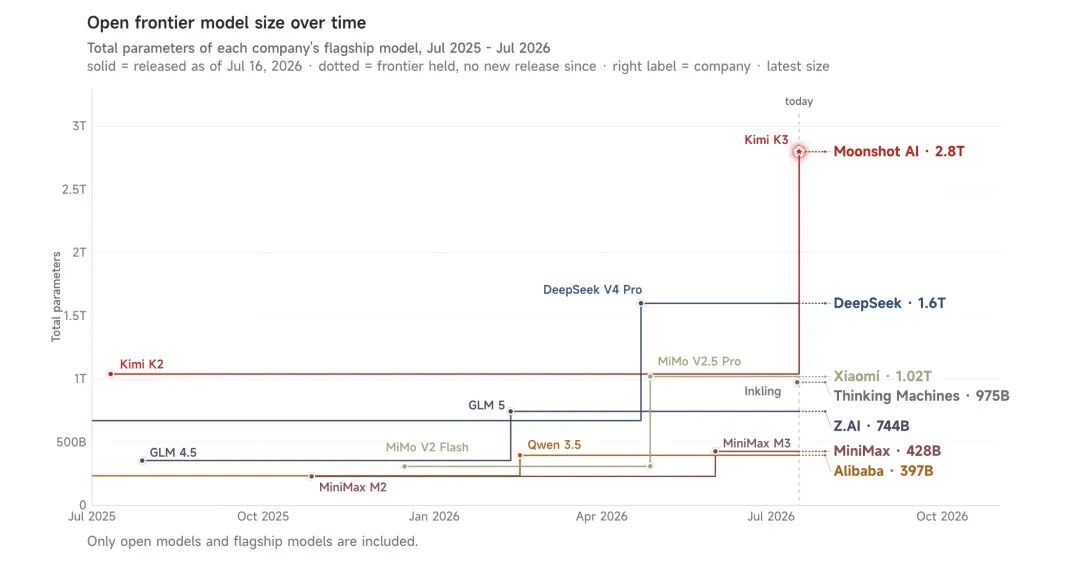
Kimi K3 is the first open-source model to reach 2.8 trillion parameters. This is the latest step in Kimi's ongoing push to expand model scale boundaries: for 9 of the past 12 months, Kimi models have held the scale ceiling among open-source models.
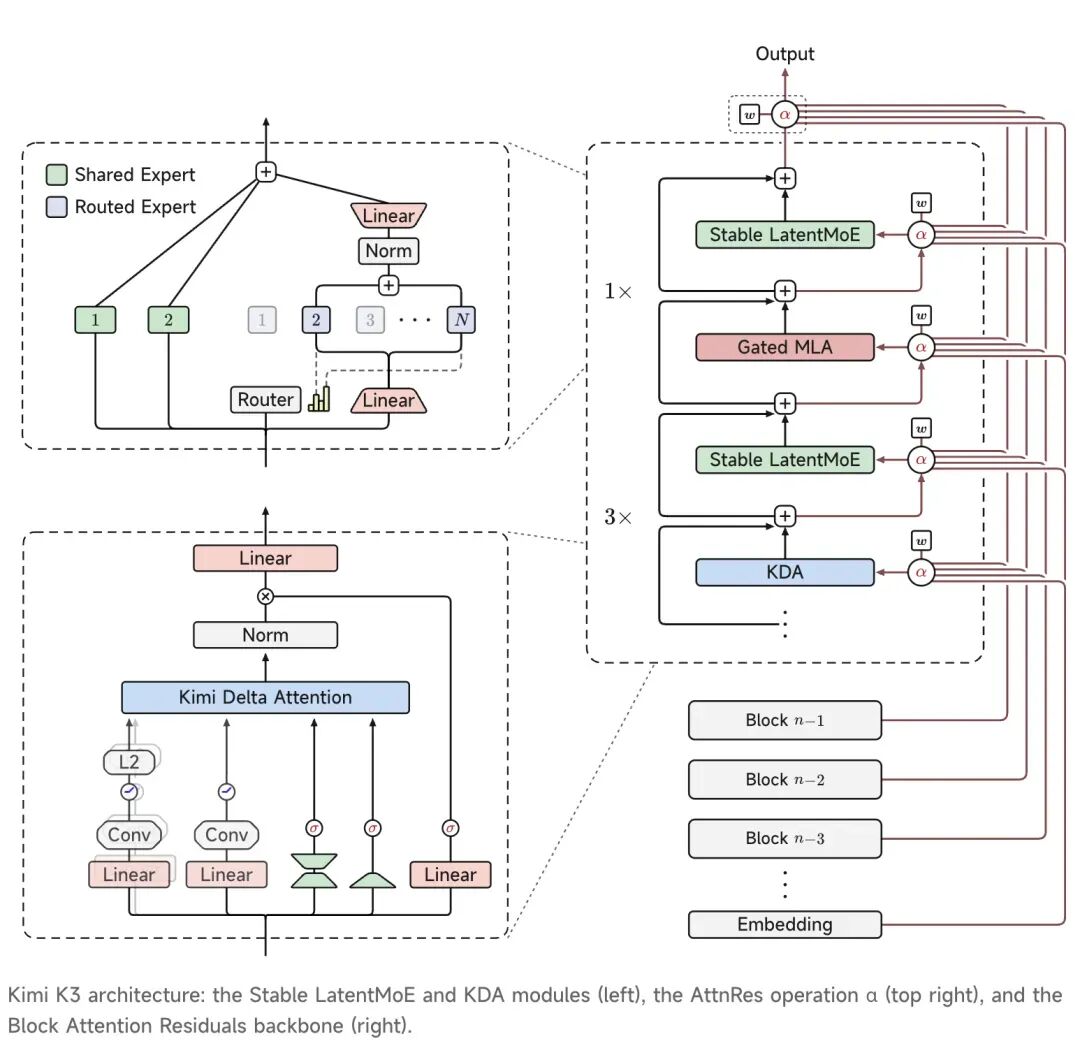
Kimi K3 is built on Kimi Delta Attention (KDA) and Attention Residuals (AttnRes). Both architectural updates are designed to let information flow more smoothly across longer sequences and deeper models. We also further expanded the sparsity of the Mixture of Experts (MoE): combined with the Stable LatentMoE framework, the model can efficiently activate 16 out of 896 experts. Together with training method and data recipe optimizations, these structural improvements give Kimi K3 roughly 2.5x better overall scaling efficiency compared to K2, more effectively converting compute into capability.
Programming
Kimi K3 possesses strong long-horizon coding capabilities. With minimal human supervision, it can sustain extended engineering tasks, understand and work with large codebases, and coordinate terminal tools.
Kimi K3 also excels at tasks combining software engineering with visual reasoning. It can leverage screenshots and visual feedback to optimize scenarios like game development, frontend work, and CAD.
The cases below demonstrate how Kimi K3 translates coding ability into open-ended software development and scientific research.
■ Kernel Optimization
We set up a kernel optimization arena to see whether Kimi K3 could truly optimize GPU kernels end-to-end. Each model ran independently in its own GPU sandbox with identical tasks, test frameworks, and production workloads. Given up to 24 hours, the model could analyze existing implementations, rewrite kernels, and iteratively benchmark results.
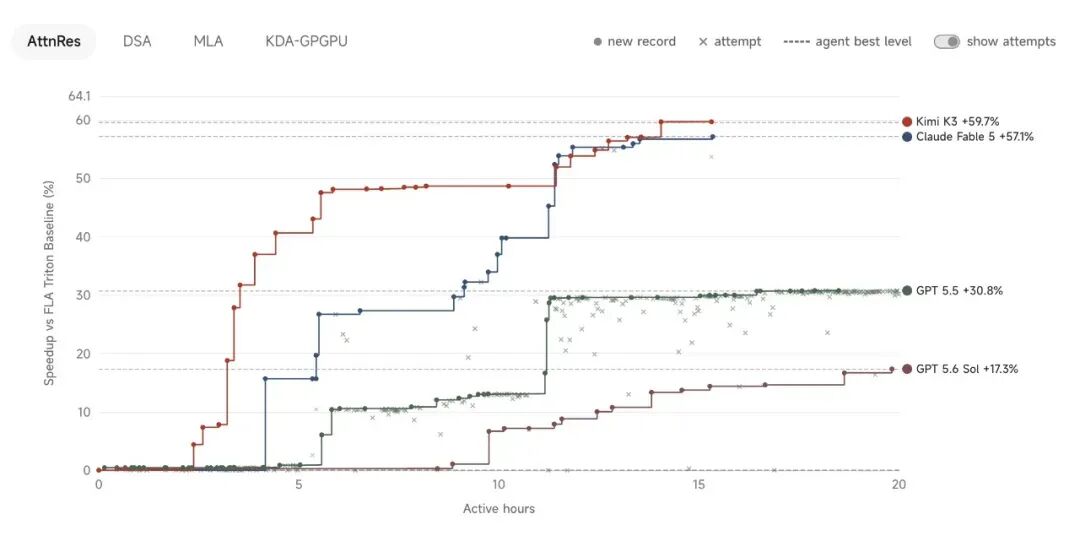
The arena spans two hardware platforms, three kernel types, and four tasks: Attention Residuals and KDA linear attention on NVIDIA H200 GPUs, a from-scratch 512-head-dimension MLA kernel, and a KDA task on a domestic GPU. At maximum thinking intensity, Kimi K3 performed close to Fable-5 (with fallback mechanisms) and clearly led Opus 4.8, GPT-5.6 Sol, and GPT 5.5.
■ GPU Compiler Development
We further tested whether Kimi K3 could build a GPU programming system from scratch. Kimi K3 developed MiniTriton: a compact Triton-like compiler. Built on MLIR, it constructed its own tile-level intermediate representation and implemented a complete optimization pass to PTX code generation pipeline.
On the Roofline benchmarks it supports, MiniTriton matched or exceeded Triton and torch.compile performance, and outperformed Triton on some workloads. It currently supports FP32 and FP64 computation; TF32 and BF16 are in development. We did not expect its early Tensor Core implementation to surpass highly optimized Triton, but the results show that without benchmark-specific shortcuts or obvious hardcoded optimizations, MiniTriton already generates competitive GPU code.
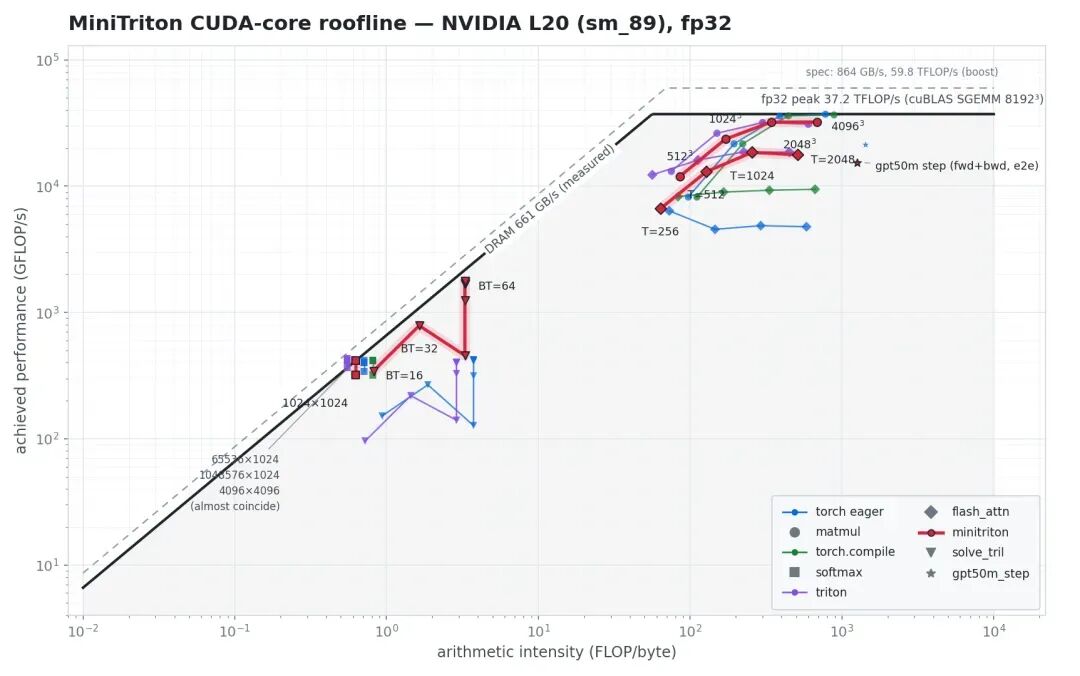
As end-to-end validation, we trained nanoGPT with TensorLite and observed normal convergence. This demonstrates that Kimi K3 did more than generate a few isolated kernels — it built a genuinely usable compiler stack: programming abstractions, intermediate representation, optimization passes, backend code generation, and integration with real training workloads.
■ Creating Digital Works
Kimi K3 fuses strong 3D reasoning, programming, and visual capabilities to transform concepts, images, and videos into fully playable interactive experiences. Seamlessly iterating between code and live screenshots, it achieves true vision in the loop — seeing output instantly and optimizing immediately.
Some examples:
▼ 3D Simulation of Long March 10 Rocket Launch and Recovery
▼ 3D Open-World Game
▼ 3D GBA Emulator
▼ Black Hole Gargantua Replication Process
■ Chip Design
As an early proof of concept, Kimi K3 designed a chip to run a nano model built on its own architecture. During 48 hours of continuous autonomous agent operation, K3 independently completed the chip's construction, optimization, and verification using open-source EDA tools and the Nangate 45nm process library. The chip spans 4 mm², integrates 1.46 million standard cells, 0.277 MB SRAM, and an INT4 MAC array with fused dequantization, achieving timing closure at 100 MHz with simulated decode throughput consistently exceeding 8,700 tokens per second. A chip designed by the model, for the model — this is the portrait of K3's long-horizon agent capabilities.
■ Scientific Research Programming
Kimi K3 can bridge scientific literature and executable code, autonomously implementing, verifying, and analyzing complex computational research workflows.
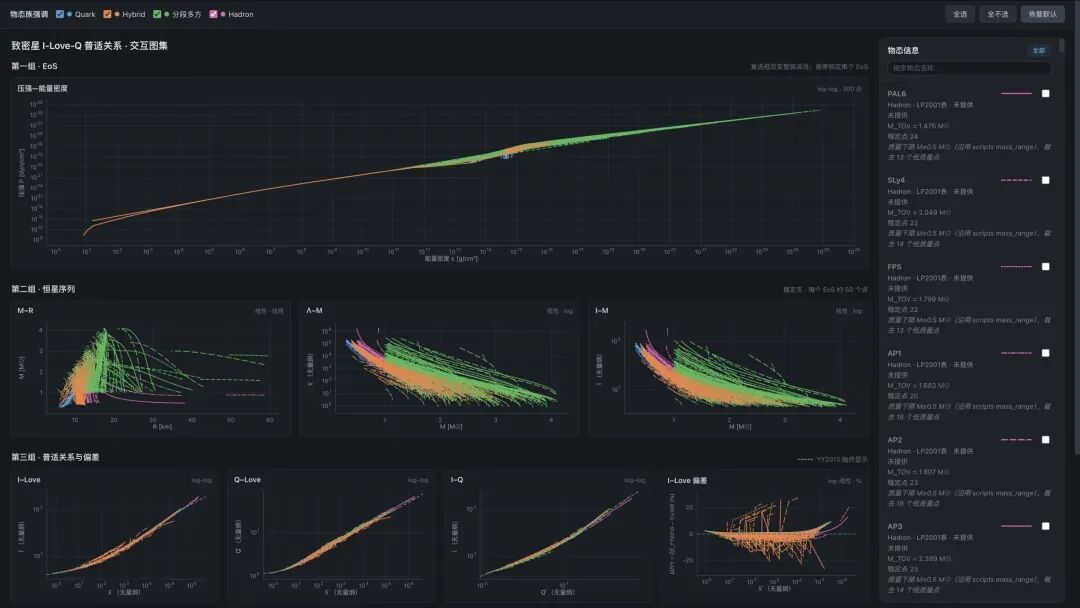
In one case, Kimi K3 completed in roughly two hours what would typically take a senior researcher one to two weeks. To reproduce the I-Love-Q universal relation in computational astrophysics, it read and cross-validated over 20 papers, implemented the complete numerical pipeline, evaluated more than 300 equations of state, discovered inconsistencies in published formulas, generated over 3,000 lines of Python code, and produced an interactive HTML dashboard for exploring results.
Knowledge Work
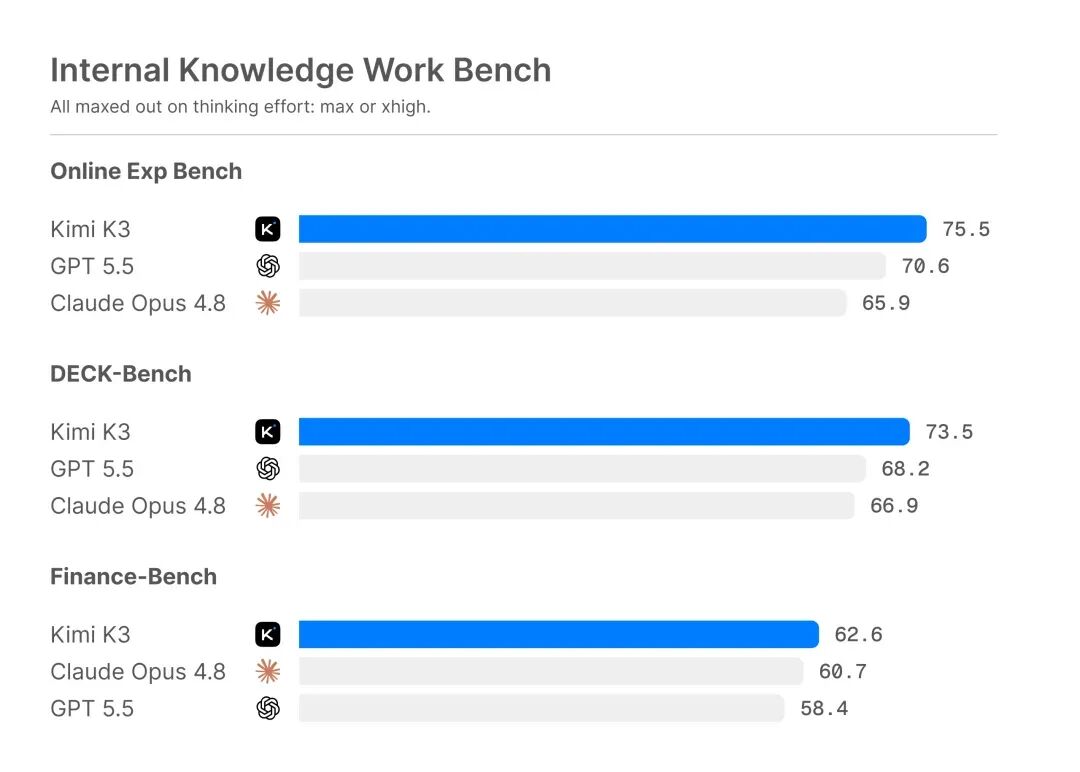
Kimi K3 advances end-to-end knowledge work. Beyond public benchmarks, Kimi K3 (max) showed steady improvement in our internal evaluations. These assessments draw from recurring task patterns and challenges in real user-agent collaboration workflows. Kimi K3 demonstrated consistent advantages across different production-scenario-oriented workflows, indicating comprehensively enhanced agent knowledge work capabilities.
■ Research and Visualization
Below are examples of what K3 in Kimi Work can accomplish in financial advisory and research scenarios.
AI Accelerator Industry Research: Covering 42 years of ASIC industry history, generated by K3 through 120+ rounds of recursive self-improvement. K3 transformed evidence into custom charts, animated diagrams, and interactive visual narratives. Throughout the process, it completed over 2,800 web searches and crawls, 1,100+ terminal data pulls, and processed 87 quarterly reports and 99 original PDFs totaling over 11,000 pages.
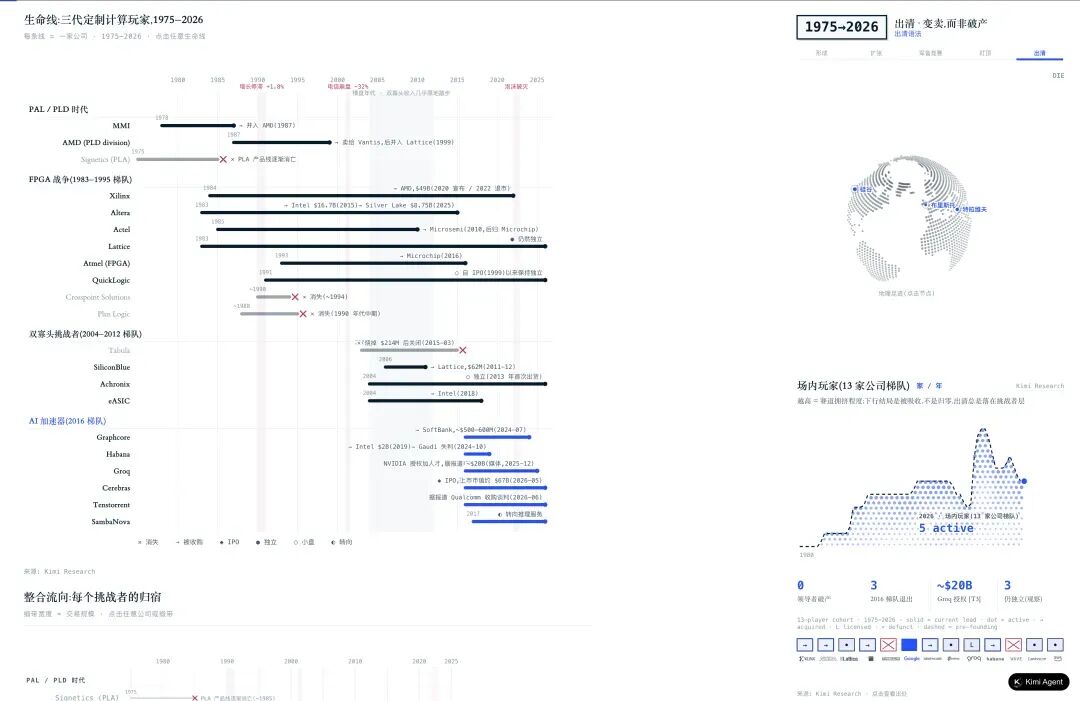
View the full interactive report: https://asic42cn.ok.kimi.link/
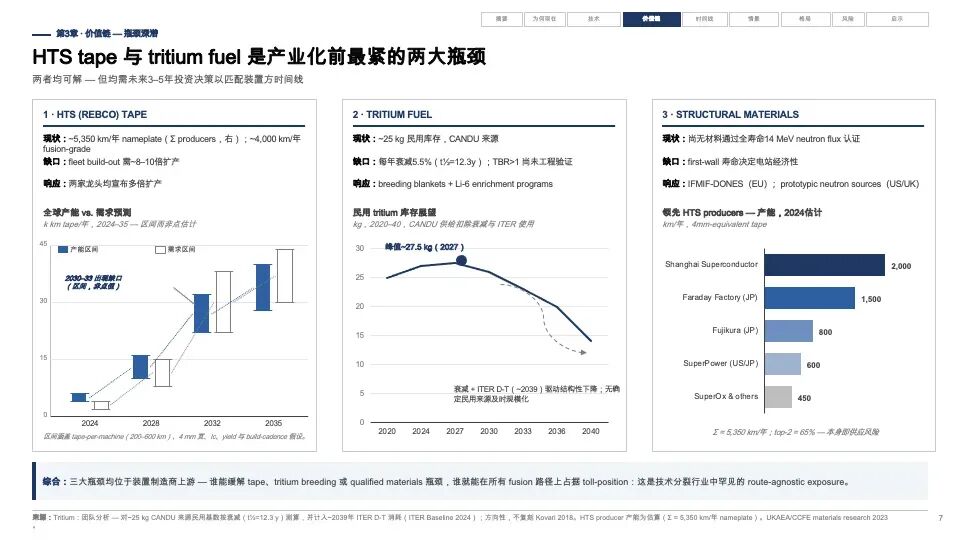
Controlled Nuclear Fusion Industry Research: A consulting-style industry report produced by K3, including timelines, tree diagrams, waterfall charts, Gantt charts, and presentation-quality slides.
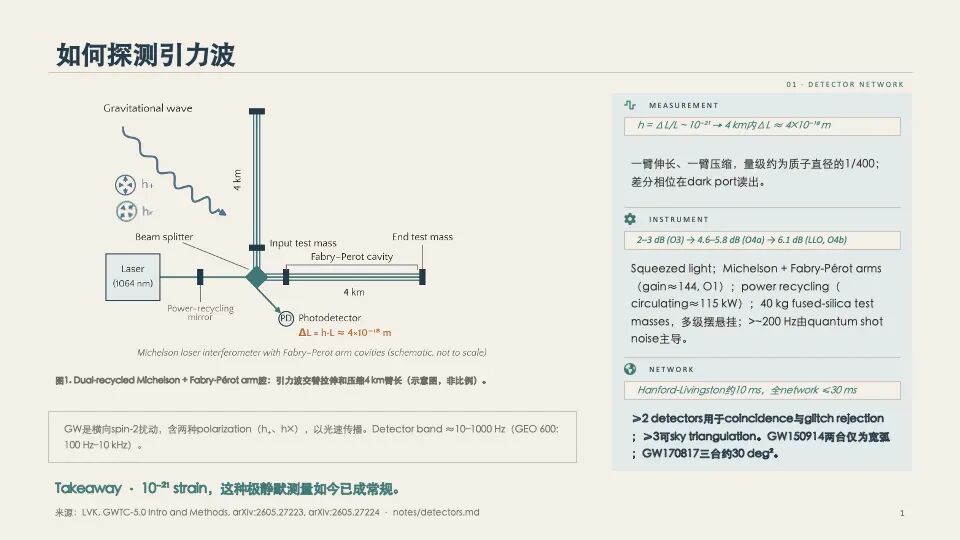
GWTC-5 Gravitational Wave Analysis: An analysis of 391 gravitational wave events using 20+ concurrent subagents, producing 7 scientific visualizations, 2 tables, and synthesizing literature from 10+ papers.
■ Widgets and Dashboards
In Kimi Work, we launched two new features: Widgets and Dashboard, making interactions with Kimi K3 more visual and persistent. Widgets can generate interactive components directly in conversation, connecting to local data or external plugins for continuous updates. Dashboards aggregate your most important widgets into a long-lasting personalized view, organized around themes, projects, or goals.
■ Video Editing
Kimi K3 excels at motion design, animation, and video editing because its native multimodal architecture understands text, images, and video within a single model.
In one case, K3 produced a "3Blue1Brown"-style motion graphics explainer video introducing its own architecture, translating technical concepts into animated diagrams and transitions, running 4.5 minutes:
In another case, Kimi K3 edited its own brand video from 56 raw clips, completing clip selection, action-matched editing, frame-accurate beat syncing, audio processing, and multiple revision rounds. A short video with this information density would typically take an experienced editor 1-2 workdays; a novice might need 3-5 days.
Architecture and Infrastructure
Kimi K3 is built on Kimi Delta Attention (KDA) and Attention Residuals (AttnRes). KDA provides an efficient foundation for attention scaling, while AttnRes selectively retrieves representations across depth rather than uniformly accumulating them layer by layer. Together they form Kimi K3's architectural backbone, enabling the model to scale beyond trillions of parameters.
Kimi K3 adopts Stable LatentMoE, actually activating 16 out of 896 experts. At this sparsity level, routing and optimization become critical challenges. Quantile Balancing allocates experts directly based on routing score quantiles, avoiding heuristic updates and sensitive balancing hyperparameters; Per-Head Muon extends Muon to optimize independently per attention head, making learning more adaptive at large scale. Sigmoid Tanh Unit (SiTU) and Gated MLA enhance activation control and attention selectivity respectively. These improvements collectively support stable, efficient training at the 2.8 trillion parameter scale.
Kimi K3 adopts quantization-aware training from the SFT stage, using MXFP4 weights and MXFP8 activations to accommodate broader hardware. To avoid throughput degradation from expert load imbalance in large-scale expert parallelism, we introduced fully balanced expert parallel training using static shapes with no host synchronization on the critical path. Since inference efficiency also benefits from larger high-bandwidth communication domains, we recommend deploying Kimi K3 on supernode configurations of 64 or more accelerators. Finally, because KDA poses new challenges for traditional prefix caching, we have contributed the corresponding implementation to the vLLM community and will release it alongside the model. With KDA plus prefill cache, we can offer Kimi K3 services at competitive token pricing even under large model scale and long context conditions.
More technical details will be published in a subsequent technical report.
Getting Started with Kimi K3
Use Kimi K3 Agents: Search for and download or upgrade to the latest Kimi app in your mobile app store, supporting iOS, Android, and HarmonyOS; or visit kimi.com directly.
Work with Kimi K3: Download the latest Kimi Work desktop client (version 3.1.0 and above), supporting Windows and Apple Silicon Macs.
Program with Kimi K3: Kimi Code runs in your computer's terminal; select the K3 model via the /model command to start experiencing it.
Build applications with Kimi API: Visit the Kimi API open platform, select kimi-k3, priced at 2 RMB per million tokens for input (cache hit) and 20 RMB (cache miss), 100 RMB for output. Leveraging the Mooncake disaggregated inference architecture, Kimi official API achieves over 90% cache hit rate for programming scenarios, making effective input pricing just 1/4 of standard input price. A top-up bonus of up to 30% is currently available.
Provide Kimi subscriptions for employees: Kimi Enterprise supports enterprise-grade data privacy protection and member management, with complete data isolation between personal and enterprise accounts. Click here to find the "Activate Enterprise Edition" button and subscribe to Kimi memberships for employees online.
Additionally, we are soon launching Kimi Hosted Agent, a managed agent platform for enterprises providing agent harnesses, isolated sandboxes, and long-task runtime environments. Join the waitlist to be among the first to participate in testing.
Limitations
-
Sensitivity to historical thinking content: Kimi K3 uses thinking history retention mode throughout post-training. If an agent framework fails to return all historical thinking content as required, or if switching to Kimi K3 from another model's ongoing session, context interference may occur, leading to unstable generation quality. We recommend using agent frameworks with verified compatibility such as Kimi Code, and avoiding switching to Kimi K3 mid-session.
-
Overly proactive: Kimi K3's training emphasized optimization for long-horizon, difficult tasks. Therefore, when encountering minor issues or ambiguous user intent during task execution, it may make unintended decisions on the user's behalf. If your application requires agents with stronger boundaries and less free rein, please impose clearer behavioral constraints on Kimi K3 through system prompts or AGENTS.md.
-
Although Kimi K3 is overall a highly competitive model, there remains a certain gap in user experience compared to Claude Fable 5 and GPT-5.6 Sol.