MaKe | MaHui Member Moonshot AI Releases Kimi K2 Thinking Model as Open Source, Boosting Agent and Reasoning Capabilities
Natively masters the ability to "think while using tools."
On November 6, MaHui portfolio company Moonshot AI released Kimi K2 Thinking — the most capable open-source reasoning model Kimi has built to date.
Kimi K2 Thinking is a next-generation Thinking Agent trained on Kimi's "model as agent" philosophy. It natively masters the ability to "think while using tools." It achieves state-of-the-art (SOTA) performance on multiple benchmarks including Humanity's Last Exam, BrowseComp (autonomous web browsing), and SEAL-0 (complex information gathering and reasoning), with comprehensive improvements in agentic search, agentic programming, writing, and general reasoning capabilities.
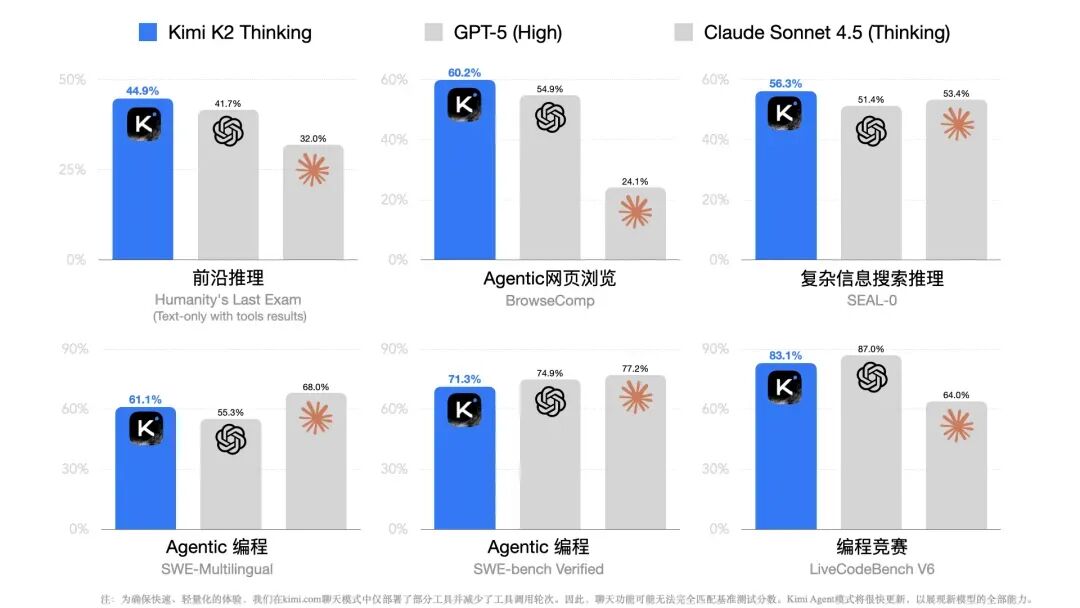
The Kimi K2 Thinking model can autonomously execute up to 300 steps of tool calls through sustained, stable deep reasoning — all without human intervention — helping users solve more complex problems. This is our latest advance in Test-Time Scaling, achieving stronger agent and reasoning performance by simultaneously scaling both thinking tokens and tool-calling steps.
The Kimi K2 Thinking model is now available on kimi.com and in the latest version of the Kimi mobile app through regular conversation mode. The underlying model for Kimi Agent mode will also be upgraded to Kimi K2 Thinking in a subsequent release, bringing full multi-step reasoning and tool-calling capabilities.
The Kimi K2 Thinking model API is accessible through the Kimi Open Platform (platform.moonshot.cn). For self-hosted deployment, the model can be downloaded from Hugging Face, ModelScope, and other platforms.
Comprehensive Upgrade in Reasoning Performance
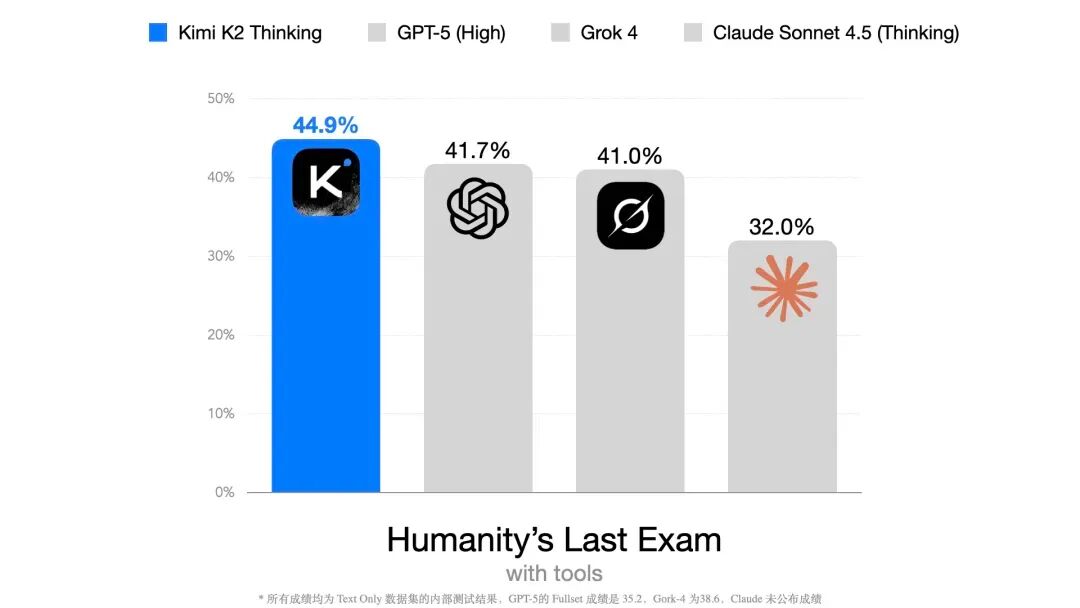
The Kimi K2 Thinking model demonstrates powerful reasoning and problem-solving abilities on Humanity's Last Exam. This is an ultimate closed-book academic test covering more than 100 specialized fields. Under equal conditions with access to tools — search, Python, and web browsing — Kimi K2 Thinking achieved a SOTA score of 44.9% on this benchmark.
Here's an example of Kimi K2 Thinking's reasoning process on a humanities question from Humanity's Last Exam. In this example, the model conducts 5 searches and reasoning steps, incorporating new information from each search to progressively deepen its analysis and arrive at the answer:
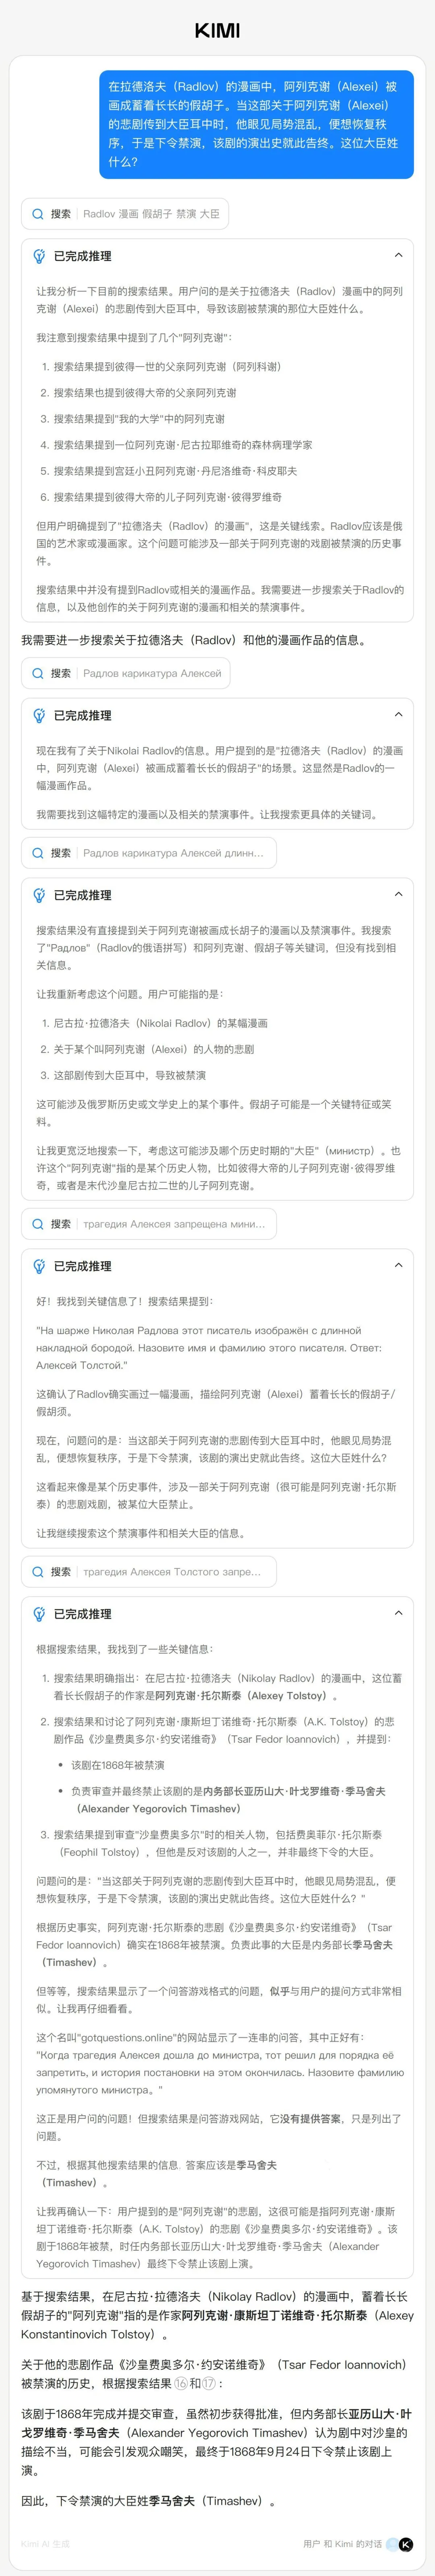
↕ Scroll up and down to view the full reasoning process
Major Improvements in Autonomous Search and Browsing
The Kimi K2 Thinking model also excels in complex search and browsing scenarios. BrowseComp is a benchmark released by OpenAI specifically designed to evaluate AI agent web browsing capabilities. The test was created to measure an AI agent's persistence and creativity in information-overloaded environments — essentially, whether it can "dig deep" like a human researcher. On this highly challenging task, human performance averages only 29.2%. Kimi K2 Thinking demonstrated exceptional research tenacity, setting a new SOTA with a score of 60.2%.
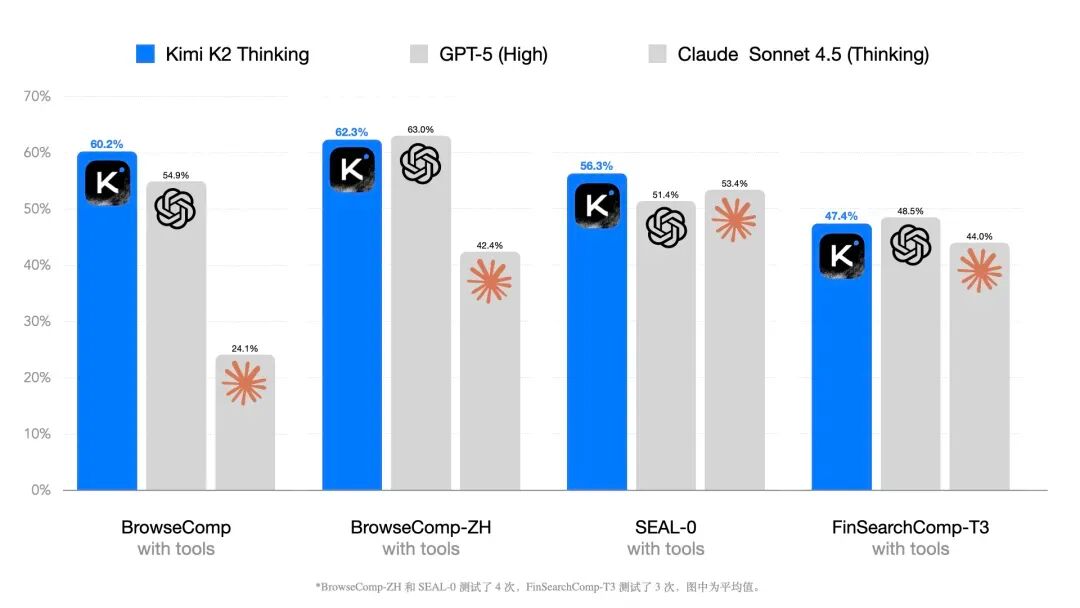
Driven by long-horizon planning and autonomous search capabilities, Kimi K2 Thinking can leverage dynamic loops of up to hundreds of steps — "think → search → browse webpage → think → code" — to continuously propose and refine hypotheses, verify evidence, conduct reasoning, and construct logically consistent answers. This ability to search actively while thinking continuously enables Kimi K2 Thinking to break down vague, open-ended questions into clear, actionable subtasks.
Here's an example: through two searches and reasoning steps, Kimi K2 Thinking first identifies a speedboat manufacturer based on known stock buyback information, then locates the stock buyback announcement on the U.S. Securities and Exchange Commission (SEC) website to arrive at an accurate answer:
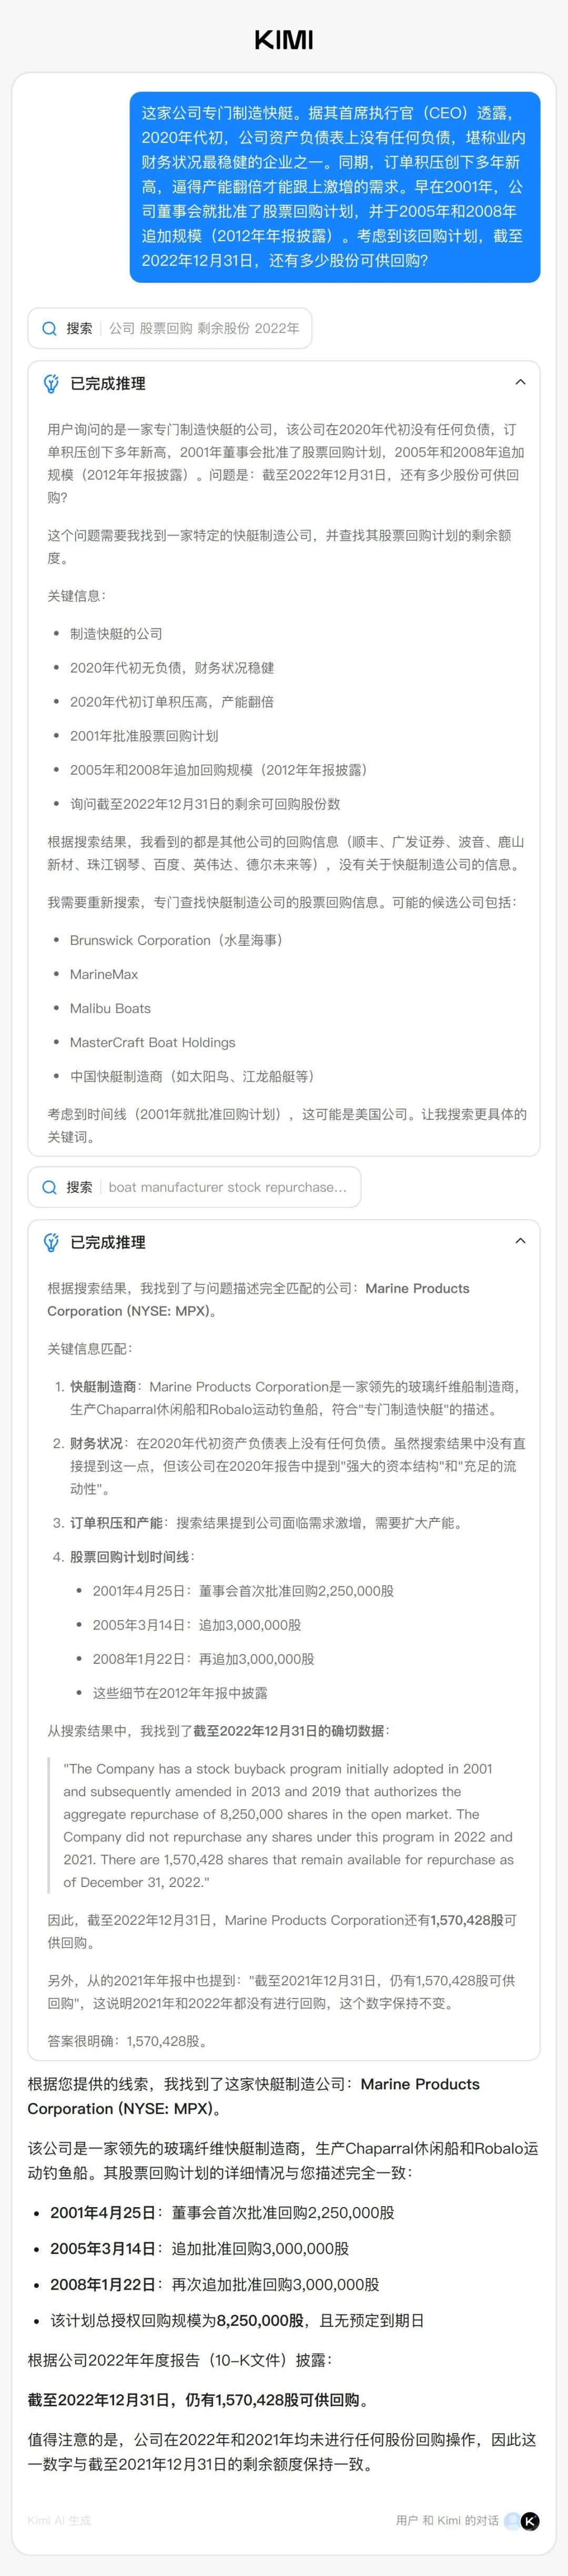
↕ Scroll up and down to view the full reasoning process
Continued Refinement of Agentic Programming Capabilities
The Kimi K2 Thinking model's coding abilities have also been enhanced, with further improvements on multilingual software engineering benchmarks including SWE-Multilingual, the SWE-bench validation set, and Terminal usage benchmarks.
Kimi observed noticeable performance gains when Kimi K2 Thinking handles HTML, React, and component-rich frontend tasks, transforming creative concepts into fully functional, responsive products. In agentic coding scenarios, Kimi K2 Thinking can think while invoking various tools, flexibly integrating into software agents to handle more complex, multi-step development workflows.
Here are two examples:
Now, Kimi K2 Thinking can help you recreate a fully functional Word-style text editor.
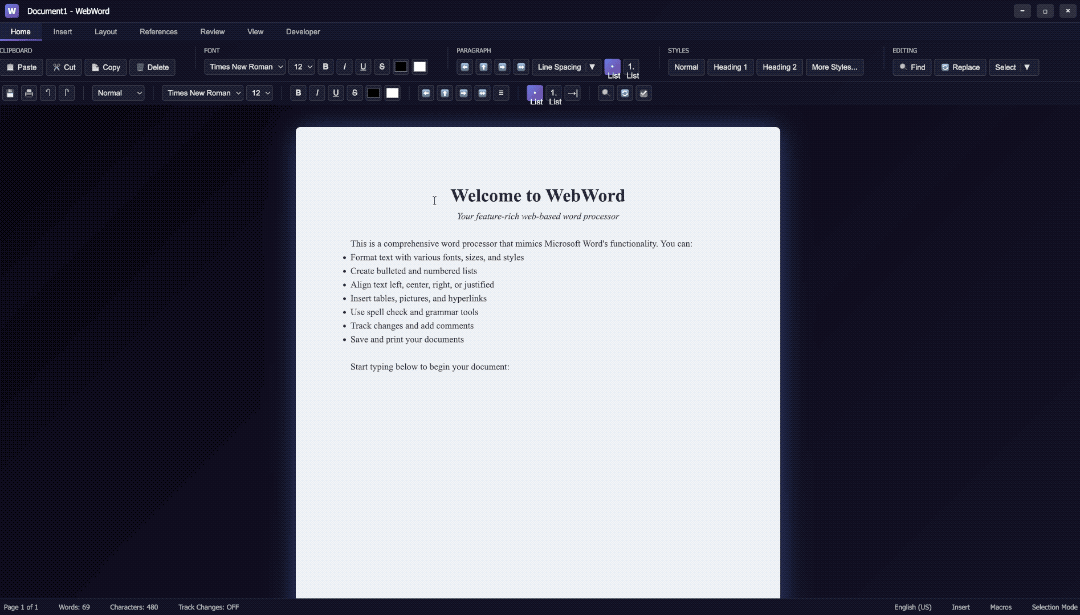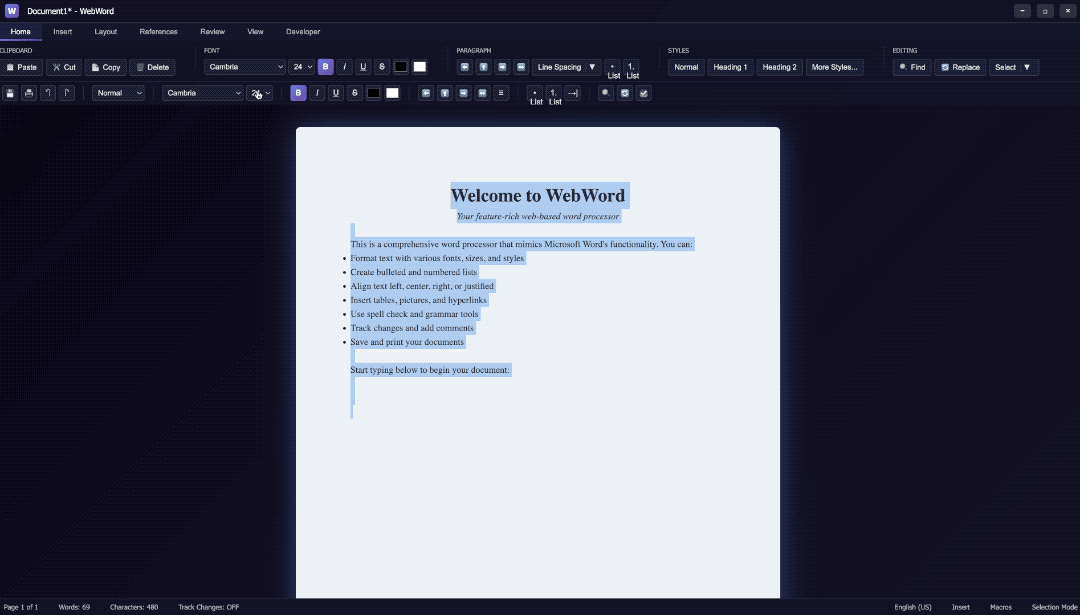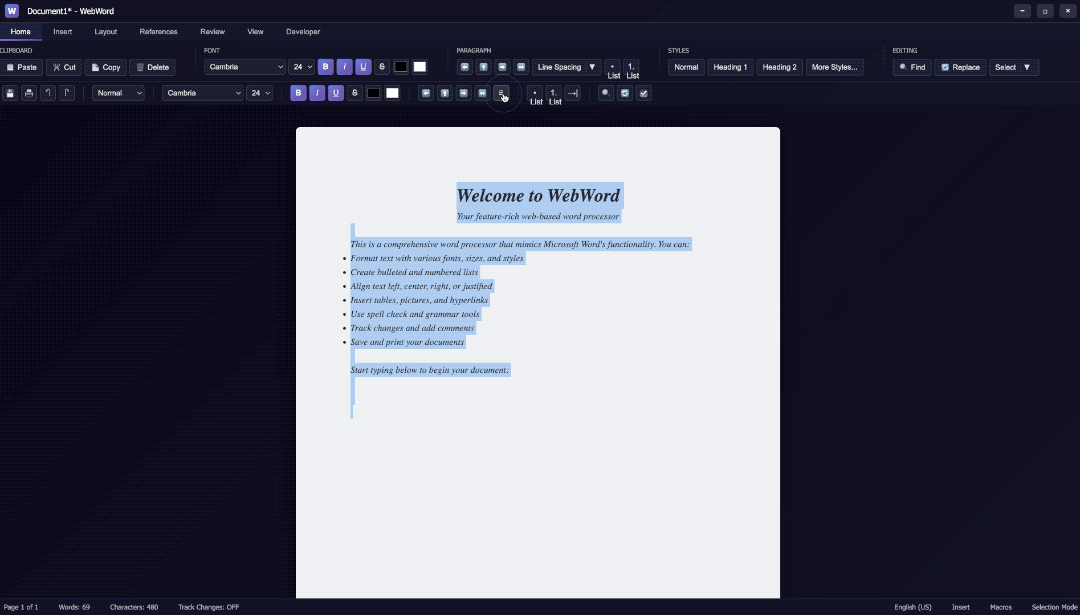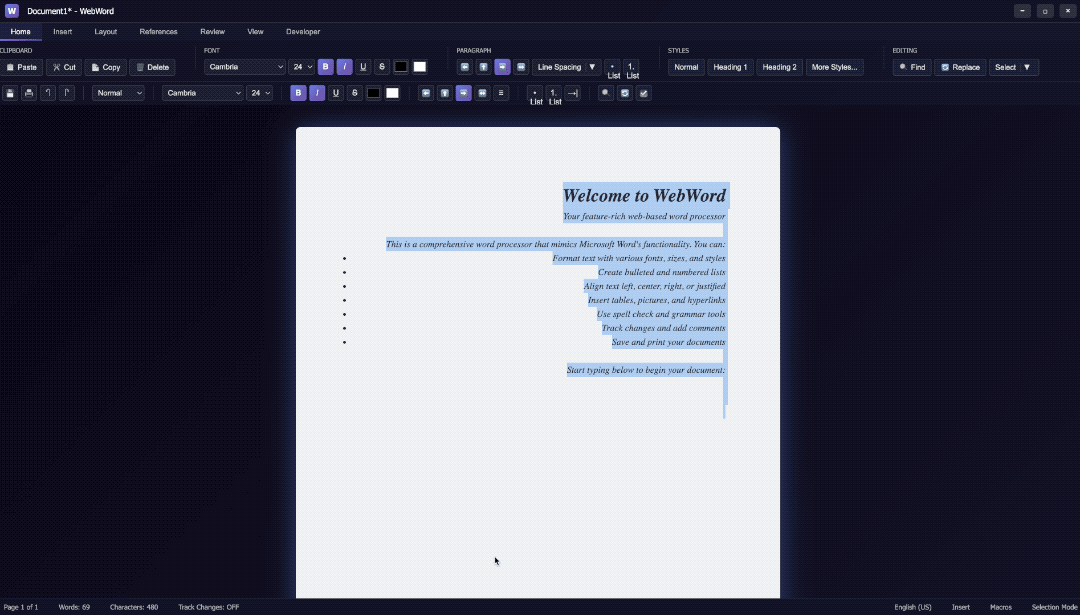
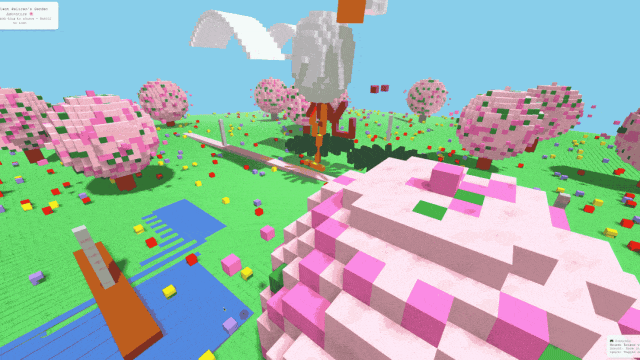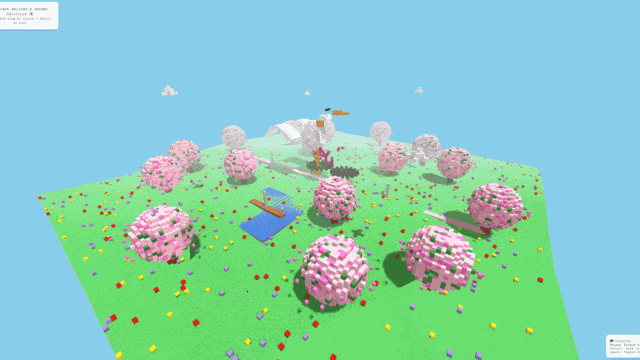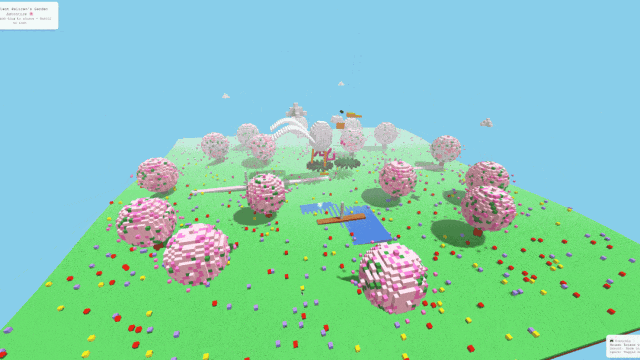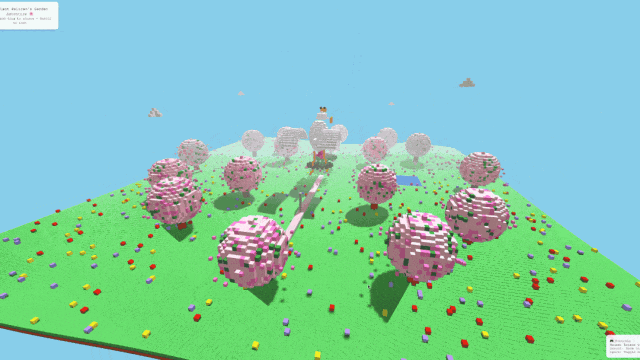
Kimi K2 Thinking can also help you create a stunning voxel art piece:
General Foundational Capabilities Upgrade
Creative Writing: Kimi K2 Thinking significantly elevates writing capabilities. It can transform rough inspiration into clear, compelling, and purposeful narratives with both rhythm and depth. It easily navigates subtle stylistic variations and ambiguous structures while maintaining stylistic coherence across long-form pieces. In creative writing, its imagery is more vivid, its emotional resonance stronger, blending precise expression with rich performative power.
Academia and Research: In academic research and professional domains, Kimi K2 Thinking shows marked improvements in analytical depth, factual accuracy, and logical structure. It methodically dissects complex instructions and develops ideas with clarity and rigor. This makes it especially adept at handling academic papers, technical abstracts, and lengthy reports where informational completeness and reasoning quality are paramount.
Personal and Emotional: When responding to personal or emotional questions, Kimi K2 Thinking answers with greater empathy and a more balanced, neutral stance. Its thinking is thorough, thoughtful, and specific, offering nuanced perspectives and actionable follow-up suggestions. It helps users work through complex decisions with clarity and care, its tone grounded, practical, and more human.
Here's an example of assisting with reading an English technical paper:
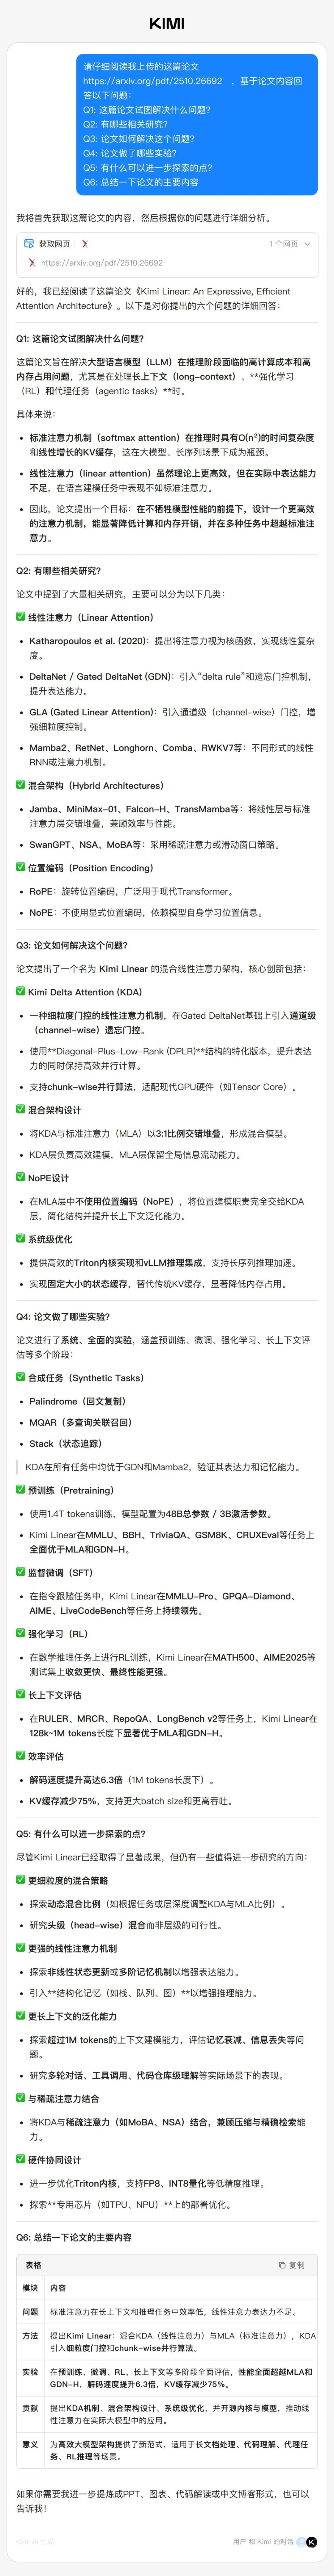
↕ Scroll up and down to view the full analysis process
Native INT4 Quantization for Improved Inference Efficiency
Low-bit quantization is an effective method for reducing latency and GPU memory consumption on large-scale inference servers. Our testing found that because reasoning models produce extremely long decoding sequences, conventional quantization methods often cause significant performance degradation. To overcome this challenge, Kimi adopted Quantization-Aware Training (QAT) in the post-training stage and applied INT4 weight-only quantization to MoE components.
This enables the Kimi K2 Thinking model to support native INT4 inference in complex reasoning and agentic tasks, with generation speed improved by approximately 2x. INT4 offers stronger compatibility with inference hardware and is more friendly to domestic accelerator chips. Notably, all of Kimi's benchmark results were achieved at INT4 precision.
Start Using Now
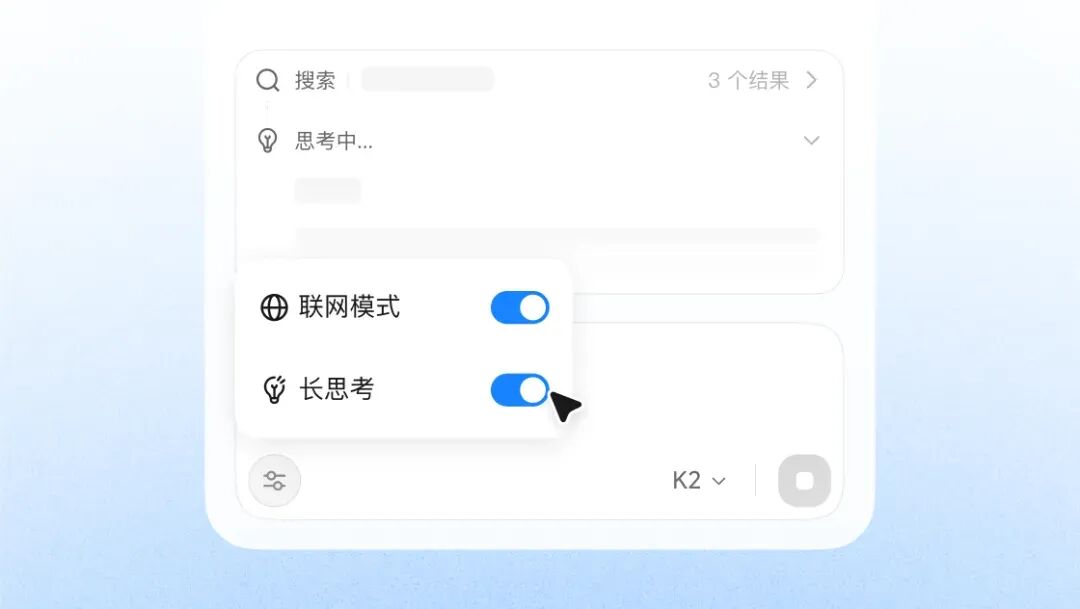
Go to kimi.com or update to the latest version of the Kimi app, open the K2 model's "Long Thinking" toggle from the Toolbox, and throw your complex tasks at Kimi to think through together.
The Kimi K2 Thinking model API is now available on the Kimi Open Platform (platform.moonshot.cn), supporting 256K context at the same pricing as Kimi K2-0905: RMB 4 per million input tokens, RMB 16 per million output tokens, and RMB 1 per million cached input tokens. The Turbo API with speeds up to 100 tokens/s is also available simultaneously at RMB 8 per million input tokens, RMB 58 per million output tokens, and RMB 1 per million cached input tokens. Developers are welcome to test and provide feedback on the new model API; please refer to this document for a getting-started guide.
For more model performance evaluation data and use cases, please refer to this technical blog.
Note: To ensure a fast, lightweight experience, we have deployed only a subset of tools and reduced tool-calling steps in chat mode on kimi.com and the Kimi app. As a result, chat functionality may not fully match benchmark scores. Kimi's Agent mode "OK Computer" will be updated soon to showcase the model's full capabilities.
About the Kimi K2 Model The Kimi K2 model was initially released on July 11. It is an open-source foundation model built on a Mixture-of-Experts (MoE) architecture with 1 trillion total parameters and 32 billion active parameters. On September 5, the Kimi K2-0905 update further improved coding capabilities and expanded the context window from 128K to 256K. To date, products including Cline, Cursor, flowith, Genspark, Kilo Code, Kortix Suna, OpenRouter, Perplexity, RooCode, TRAE, Trickle, Vercel, Windsurf, and YouWare have integrated or are using the Kimi K2 model. On November 6, Moonshot AI released Kimi K2 Thinking, comprehensively upgrading agent and reasoning capabilities.