MaHui Entrepreneur | Xingxing Wang: The Biggest Barrier to Mass Humanoid Robot Deployment Is Embodied Artificial Intelligence
MaHui portfolio company Unitree founder and CEO Xingxing Wang shared his latest observations and insights on the global robotics industry at World Robot Conference 2025.
- This article was originally published by "Zhidx" (智东西), written by Junda Chen, edited by Shuiqing Li.
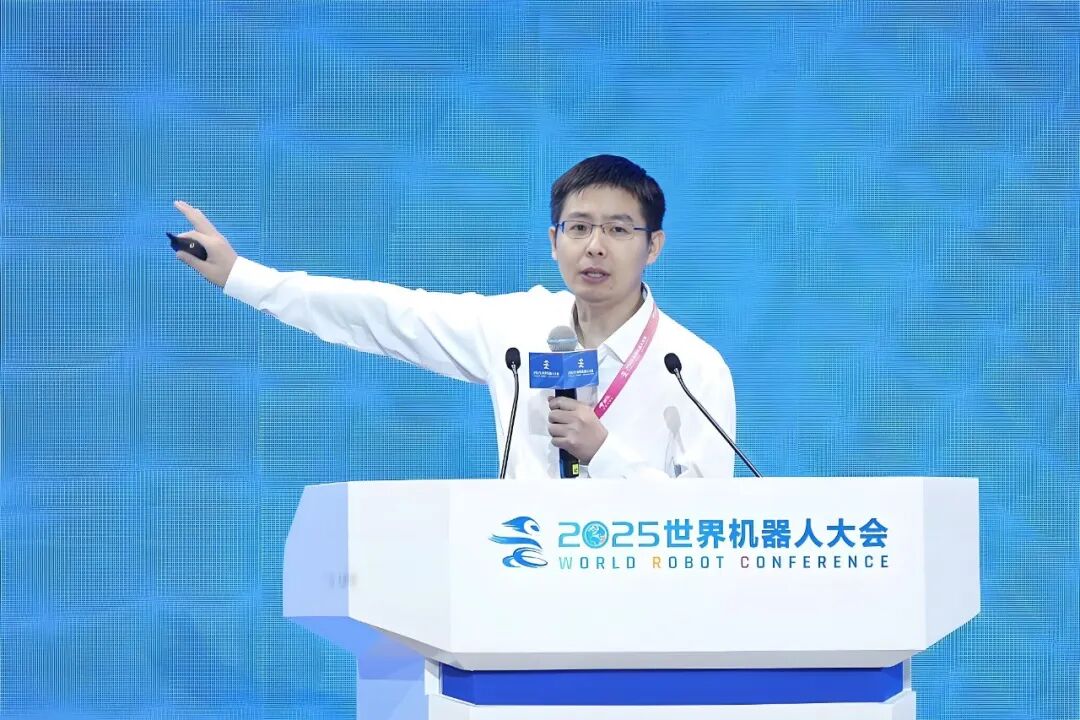
From August 8–12, the annual World Robot Conference took place in Beijing's Yizhuang district. This year's theme was "Making Robots Smarter, Making Embodied Intelligence More Intelligent," drawing over 200 domestic and international robotics companies — with humanoid robot makers setting a record for any similar exhibition globally.
At the conference, Xingxing Wang, founder and CEO of Unitree — a MaHui portfolio company — delivered a keynote speech sharing his latest observations and unique perspectives on the global robotics industry's development.
Below are excerpts from Wang's presentation:
I'd like to share my personal views on the global humanoid robot market. The biggest feature of the first half of this year was that, driven by the industry's explosive growth and supportive policies, both complete-system manufacturers and component suppliers achieved average growth of 50% to 100%. That growth rate is pretty staggering — extremely rare for the industry as a whole. Demand is pulling the entire sector forward.
On overseas markets: Tesla, as the industry bellwether, plans to mass-produce thousands of humanoid robots this year and will release its third-generation Optimus. That's worth watching closely. Beyond that, global corporate enthusiasm for robotics is running high — NVIDIA, Apple, Meta, OpenAI, and others continue to push this field forward.
I'll share a few personal opinions. They may not be right.
First, regarding robot hardware itself, many people have this misconception: that the reason robots aren't widely deployed yet, that their capabilities aren't fully developed, is because the hardware isn't good enough or costs too much.
Actually, current hardware — whether complete systems or dexterous hands — is more than adequate in a sense. Of course it's not perfect and needs optimization, and the bigger issue is mass production, which definitely presents plenty of engineering challenges.
But from a technical standpoint, or from an AI perspective, current hardware is completely sufficient. The biggest challenge right now is embodied intelligence, or rather AI technology development — it's completely inadequate. This is the main constraint on current robots, especially humanoid robots, achieving large-scale deployment.
In the years before ChatGPT emerged, voice AI had been under development for over a decade, nearly two decades. But everyone kept thinking it was dumb, idiotic, completely unusable. When ChatGPT came out, it achieved capabilities beyond the average person. Robotics hasn't reached that tipping point yet.
For robot AI technology, I think the tipping point might look like this: when a humanoid robot can enter a completely unfamiliar environment — say, a conference venue it's never seen — and I tell it "take this water bottle to that audience member" or "tidy up this room," and it can smoothly complete the task autonomously. That would be the ChatGPT moment for humanoid robots.
If progress moves quickly, we might achieve this in 1–2 or 2–3 years; at the slowest, there's a strong probability of getting there in 3–5 years.
Right now, regarding the inadequacy of embodied intelligence — is it a model problem or a data problem? I actually feel that globally, attention on robot data is somewhat overblown. The biggest problem right now is actually models, not data.
For embodied intelligence and robotics, model architectures aren't good enough yet, and they aren't unified enough. People are highly focused on the model problem, yet somehow paying lots of attention to data. Because in the large language model field, the thinking is: if I have enough data, especially enough good data, I can train increasingly better models.
But in embodied intelligence, in robotics, you find that in many cases, having data doesn't mean you can actually use it.
What's relatively hot right now is VLA models. VLA is a relatively simplistic architecture, and I personally remain fairly skeptical of VLA models. When VLA models interact with the real world, the data quality and the data that can be collected are somewhat inadequate.
A simple idea is to add RL training on top of VLA models — that's a very natural thought. But personally, including based on our company's current attempts at VLA plus RL training, I feel it's still insufficient. The model architecture itself needs further upgrading and optimization.
Let me briefly share some things we've done. You may have noticed that Google released their next-generation video generation model, or in a sense, a video-driven world model. Also, last year when OpenAI released its video generation model, a very natural idea emerged: could I control a video generation model and tell it "generate a robot tidying up a room for me"?
If the robot in the generated video can complete the task, could I then have this video generation model directly drive a real robot to complete the task? The idea is very simple and direct — we went and did this last year.
You can see, the video in the upper right is generated, not captured by camera. We took a pre-trained video generation model, retrained it to first generate a video of robot movements, then control a real robot to execute them — this technology is achievable. Including Google's video generation world model, they're also trying to achieve this effect.
I think this approach may develop faster than VLA models, with higher probability of convergence. But I can't guarantee it — there may still be many problems. One major issue is that video generation models focus too heavily on video generation quality, leading to fairly heavy GPU consumption.
For robots doing actual work, in a sense you don't need very high-precision video generation quality — you just need to drive the robot to get the job done. You can look at Google's video generation model, it's still quite interesting. The overall model architecture is very crude and direct — it simply aligns robot action sequence controls to the model architecture.
Another point: as you know, robots dancing, doing combat sports — the effects are actually pretty good now. But there's a major problem facing further capability improvement, namely RL Scaling Law for robots, which is still being done very poorly.
Take the simplest example: when I train a robot to do a new movement, a new dance, I have to retrain from scratch. That's a very bad situation. What we want is that each time a robot does new training, it can build on past training.
Theoretically, when I do RL training, each training session should get faster, and learning new skills should get better. But across the entire industry right now, no one has achieved or done well on RL Scaling Law for robots. I think this is a very worthwhile direction.
Because RL Scaling Law has already been fully validated on language models. But for robot motion control, everyone's just getting started.
I personally feel that in the next 2 to 5 years, the focus of intelligent robotics technology will be end-to-end embodied intelligence AI models. I think the model itself is the most important thing.
Then there's lower-cost, longer-lifespan hardware — that's unquestionable. As you know, even for the automotive industry, over a hundred years old, even today, the engineering effort for a company to build a really good car is still enormous.
For the robotics industry, if in the future we're producing millions, tens of millions, or even hundreds of millions of humanoid robots annually, the engineering challenges will be truly staggering.
At the same time, low-cost large-scale compute is also important. On humanoid robots, or mobile robot platforms, you can't directly deploy large-scale compute. The form factor is only so big, the battery is only so big, there's a limit to compute deployment power consumption.
I personally feel that on humanoid robots, you can deploy at most compute with peak power consumption of 100 watts; during normal operation it's only a few dozen watts — simply put, roughly the compute level of a few smartphones.
But future robots will still need large-scale compute, and I think it may be distributed compute. When robots are working, we want relatively low communication latency — if a robot is working in Beijing and the data center is in Shanghai or Inner Mongolia, the latency is simply too high.
I personally feel that when humanoid robots are deployed at scale in industrial settings in the future, factories could have distributed servers, with all robots directly connected to local servers within the factory. Server security and communication latency would be acceptable.
Or to put it another way, if every household in a residential community has a robot, that community might have a distributed cluster compute center that can guarantee latency and security. And when a new customer wants to buy a humanoid robot, they don't need to pay for this compute infrastructure, making costs much lower.
I think distributed compute will be a very important area for the robotics industry's future, possibly even more widely distributed than current compute infrastructure.
Another point: as you know, the AI and robotics fields have always been a process of global co-creation. Chinese companies, American companies, including NVIDIA and others, have already made many contributions.
In AI, no large company can guarantee that with enough people and enough resources, they can stay ahead forever. OpenAI and DeepSeek have proven that AI innovation always involves some randomness, always involves more smart young people. So in many cases it's contributions from many companies and universities — it still has to be globally co-created. Thank you.