10 Q&As: A Deep Dive into the Divisions Surrounding Embodied Robots | Yunqi Capital X Crossing
The Battle for Data, the Battle for Intelligence, the Battle for Scenarios
Not long ago, at the 2026 Inclusion Conference on the Bund, there was a panel titled "Physical Intelligence — Divergence and Decisions," moderated by Koji from Crossing. The four guests came from Sudu Tech, Ant Lingbo Technology, Independent Variable Robotics, and Poke Robotics — Sudu Tech, Independent Variable Robotics, and Poke Robotics are all early-stage portfolio companies of Yunqi Partners.
The discussion put three fault lines in embodied AI on the table: whether data should come from simulation or real robots, whether Astra poses a dimensionality-reduction strike on embodied AI, and which metrics can prove embodied AI has crossed through the bubble. At the end, each of the four answered what, five years from now, will look overhyped and what will look underestimated.
In this edition of "Yunqi Partners", we share 10 key Q&As on embodied AI worth your attention right now. Enjoy.
The following is adapted from the WeChat public account "Crossing."
Moderator: Koji | Editing and compilation: Crossing
This was a rare public discussion about route-level divergences in embodied AI — one that did not converge.
In 2026, embodied AI doesn't lack heat. What's missing is people willing to put the disagreements on the table. Where does the data come from? How should models be built? Where does deployment land?
If OpenAI or Anthropic enters embodied AI, would that be a dimensionality-reduction strike? Where do Astra's capability boundaries lie? Making building an airplane as easy as building an app — fantasy or within reach?
On the morning of September 10, at the 2026 Inclusion Conference on the Bund, a panel discussion on "Physical Intelligence — Divergence and Decisions" took place. Moderated by Koji, the panel included Zheng Han, co-founder and CEO of Sudu Tech; Yujun Shen, chief scientist at Ant Lingbo Technology; Qian Wang, founder and CEO of Independent Variable Robotics; and Huazhe Xu, founder of Poke Robotics and assistant professor at the Institute for Interdisciplinary Information Sciences, Tsinghua University.
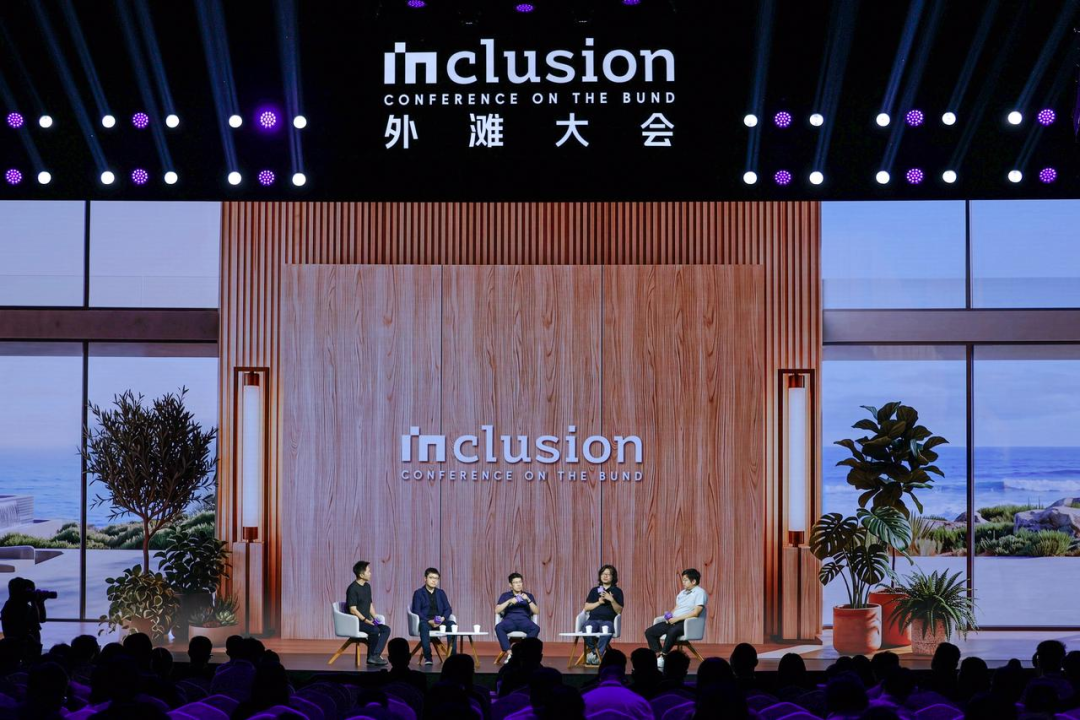 2026 Inclusion Conference on the Bund | "Physical Intelligence — Divergence and Decisions" panel
Through this conversation, you'll learn: 1) the core assumptions and risks of different technical routes; 2) how to judge which metrics are leading indicators; 3) the difficulty language model companies face entering embodied AI, and where startups' moats lie; 4) the short-term vs. long-term logic of embodied AI commercialization; 5) which areas are overhyped or underrated — and the corresponding investment opportunities or risks.
When an industry stops arguing about "what's right" and starts proving "what's feasible" with products and deployments, a sector has truly entered the phase of moving from bubble to industry.
Listen on Xiaoyuzhou:
🎬 The video is also live on @Koji杨远骋's WeChat Channels, Xiaohongshu, Bilibili, YouTube, and other platforms:
Below is the edited transcript of the conversation.
The Data Debate: Simulation or Real Robots?

👦🏻 Koji (Crossing) Let's get straight to it. Today we'll cover three topics: the data debate, the intelligence debate, and the scenario debate.
Why all these "debates"? Because in 2026, we're standing at a crossroads with many paths that haven't yet converged, waiting to be explored.
The first question goes to Mr. Han: on data, some are betting on simulation, others are firmly betting on real robots. You've firmly bet on simulation. What signals did you see back then? And today, what new reinforcing signals are there?
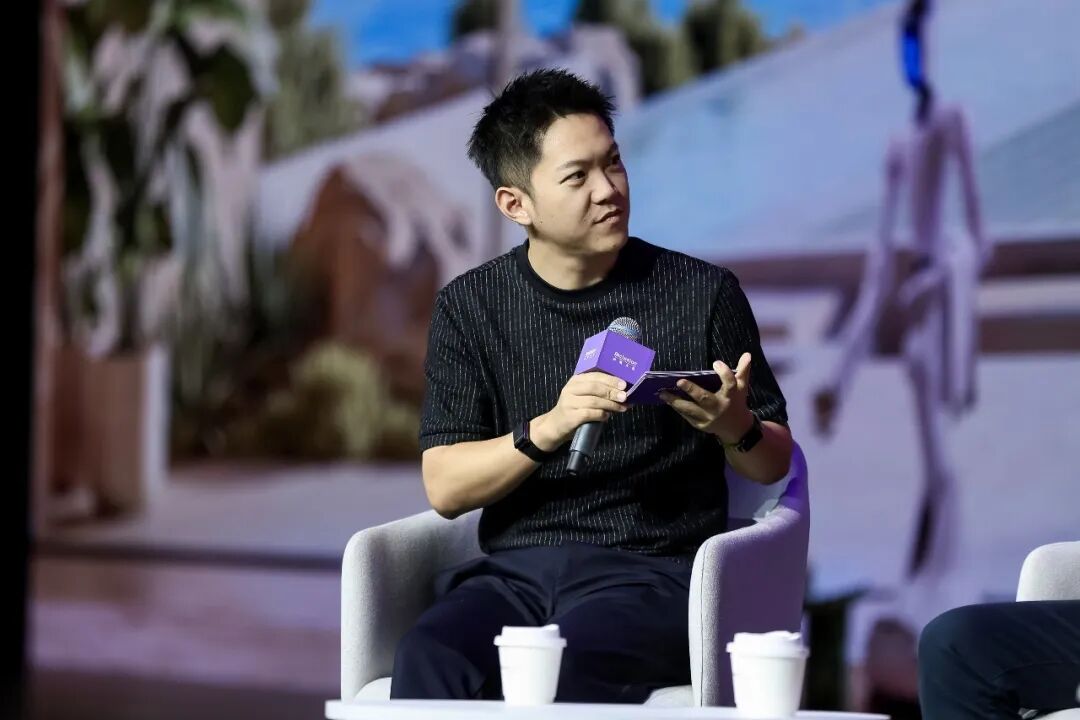
Koji, founder of Crossing
👨🏻💻 Zheng Han (Sudu Tech)
We firmly believe in using simulation — but at the same time, we also firmly believe real-world data is extremely valuable.
Our starting point was fairly simple. We began building robot simulators and synthetic data back in 2015 and 2016, then founded the company to build a commercial version. We've been through two rounds of iteration.
First, research and commercialization are different. In research, you can run experiments with open-source projects, data, and algorithms. But typically, after people try it out, they don't know how to modify the technical model at scale, so they just stop there.
The reality is that model-based reinforcement learning and large-scale pretraining — whether it's the simulators we open-sourced earlier, like CPM and Skill, or NVIDIA's Isaac — all have certain limitations, as we see it internally.
So after 2024, we committed to building a large-scale, fully re-architected closed-source system, including the data pipeline and the simulator pipeline — simulation, model-based reinforcement learning, and large-scale reinforcement learning inside the simulator.
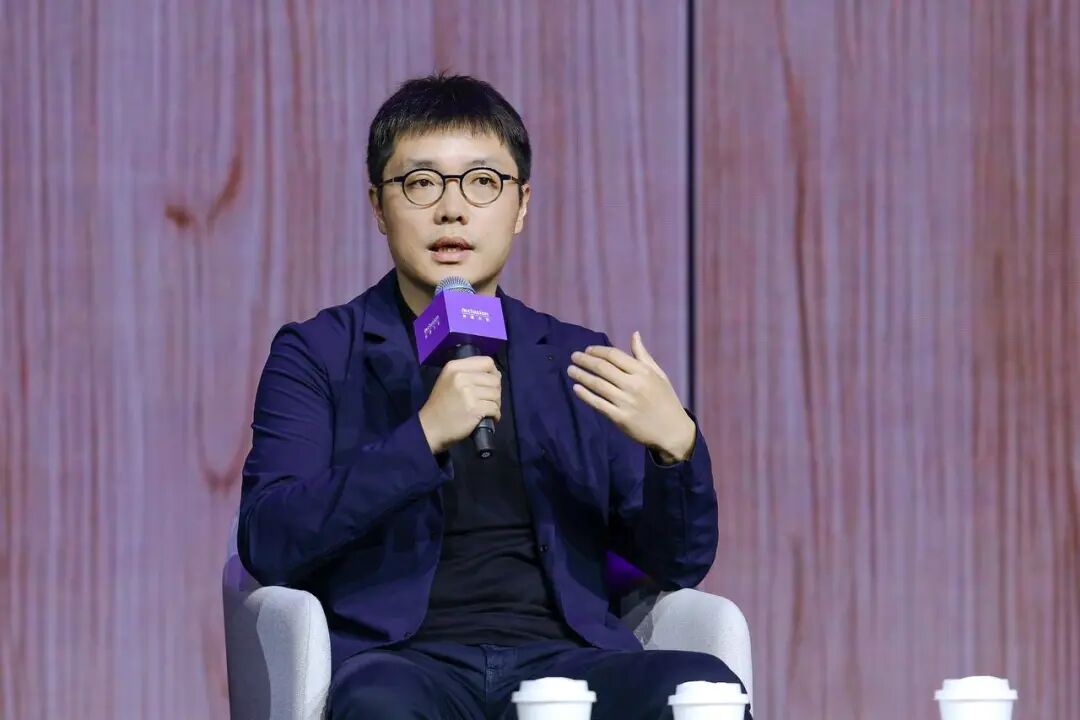 Zheng Han | Co-founder and CEO of Sudu Tech
In a demo this April, we showed that for certain skill operations under strong generalization across combinations of objects, environments, and lighting — tasks like grasping, placing, and assembly — we can achieve nearly 100% success rates with almost no restrictions on objects or environments.
On data, our conviction is this: simulation is unavoidable. Relying solely on real-world data collection is slow, and the quality is sometimes limited.
Recently, some peers in the United States have also started strengthening their simulator capabilities. Their approaches differ, but it's a signal to the industry.
👦🏻 Koji (Crossing)
Lingbo has clearly chosen real data as its data route. Mr. Shen, in your view, what aspects of real data can simulation not replace? What's the biggest value it provides compared to simulated data?
👮🏻♂️ Yujun Shen (Ant Lingbo Technology)
I wouldn't say we firmly chose real data. We've never believed you must choose one type of data or must reject another.
Different data plays different roles at different stages. For example, in the pretraining stage, we believe internet data and data collected from the real physical world may matter more. But when it comes to a specific task, simulated data is still valuable — autonomous driving is a case in point.
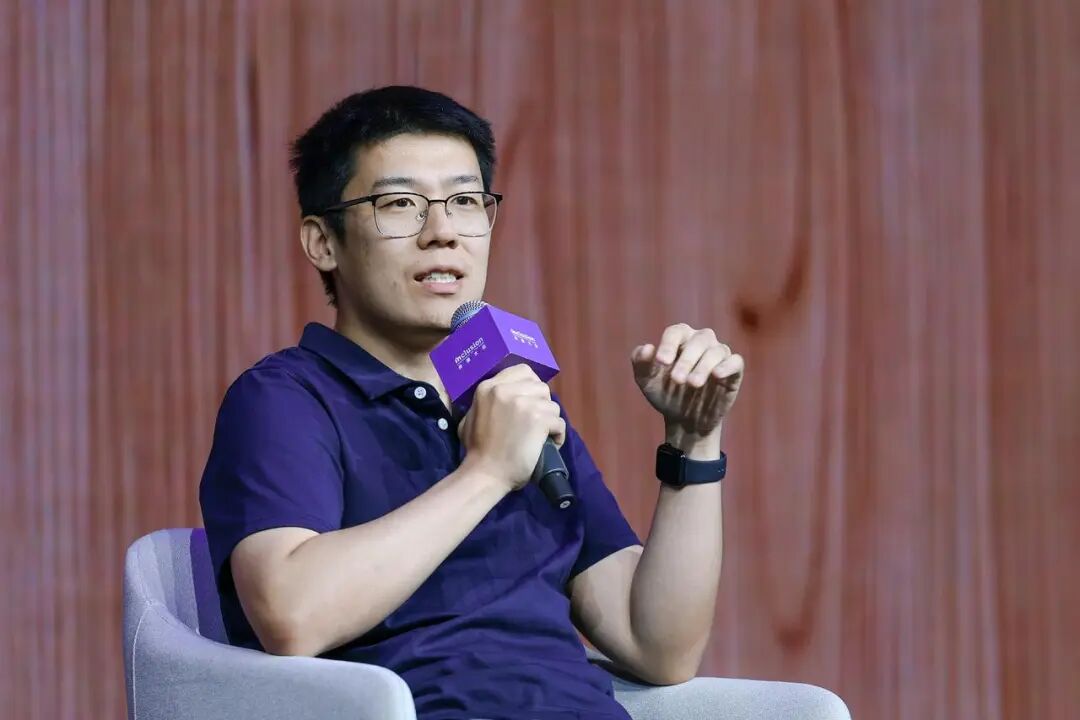 Yujun Shen | Chief Scientist at Ant Lingbo Technology
Why do we insist that during pretraining, some data should come more from real scenarios?
Imagine one day a robot actually comes into the real world to work. Its way of working differs from working in the digital world. Its only observations must come from the sensors on its body — we can't plug a keyboard into a robot for typed input. But real-world sensors always have errors. There are no perfect sensors; that's a physical constraint. Under these conditions, the robot can only rely on its own sensors as input to do its work.
Simulation may currently have a problem. People talk a lot about the Sim-to-Real gap, but from first principles, I think the bigger issue is actually the scalability of Real to Sim.
In other words, can we really move sensor noise and other lower-level phenomena faithfully into the simulator — and can that process be replicated at scale? If Real to Sim can't be scaled, then just talking about gradually shrinking the Sim-to-Real gap may not be very valuable.
As for which data must come from the real world and can't be replaced by simulation — at a deeper level, it's because robots must work in the physical world, and many of the physical world's imperfections are hard to simulate.
👦🏻 Koji (Crossing)
Give a concrete example — what kind of imperfection is really hard to reproduce in a simulator?
👮🏻♂️ Yujun Shen (Ant Lingbo Technology)
Tactile information, tactile signals, for example.
Many tactile sensor companies now offer tactile simulation, but we've tested it: the signals captured by real sensors often differ drastically from the simulated ones.
Signal frequency, amplitude, consistency across sensors — these are all very hard to replicate faithfully in a simulator.
The Intelligence Debate:
Will Astra Crush Embodied AI from a Higher Dimension?
👦🏻 Koji (Crossing) Since GPT-6's Astra launched, social media has been flooded with tests of people using Astra to control robotic arms for all kinds of tasks. There's even a claim going around that embodied AI is about to be crushed from a higher dimension by general-purpose large language models. Qian, how did you feel when you saw those videos?
💂♂️ Qian Wang (Independent Variable Robotics)
This is definitely the hottest topic in the industry right now. Just this morning I saw another video of Astra controlling a dexterous hand.
This version of the model was actually trained on a large amount of robotics data. Since early last year, OpenAI and Anthropic have been purchasing robotics data at scale, and they each run small data factories collecting robotics data themselves. So this isn't particularly surprising — it was within expectations.
Qian Wang | Founder and CEO, Independent Variable Robotics
I've long held a somewhat controversial view, but I think colleagues working on the front lines of large models would agree:
Today, the substance of intelligence lives in the data — and partly in evaluation. The model is more like a distiller and a container: during training it's a distiller; during deployment it's a container.
If you want to build a frontier AI system today, the role of the model itself has actually become extremely small. The bigger factor is data — you need ever-better data. How to create data, select data, validate data, annotate data — these are exactly the things driving AI systems forward.
So the question becomes: if OpenAI and Anthropic want to do embodied AI, do they still need the same data infrastructure, validation infrastructure, and other infra that we rely on? Do they still need to collect data from the real world, build simulators, run evaluations in the real world, integrate with hardware, and so on?
If they still have to do all these things, then they're just another embodied AI company. Because none of these difficulties diminish just because they have an advantage in foundation models. If anything, embodied AI companies may hold a substantive advantage.
👦🏻 Koji (Crossing)
So you don't believe GPT-6 Astra will crush the embodied AI industry from a higher dimension?
💂♂️ Qian Wang (Independent Variable Robotics)
The essence of what people worry about is this: could large language models generalize their general intelligence from other domains into embodied intelligence, and thereby crush it?
I think that's unlikely.
First, this has never happened in the history of language models. The same is true of recent work on 3D, and of computer use — even though video generation models are excellent today, that hasn't directly translated into a natural advantage at the action level or the robot-control level.
Conversely, the lesson for us is this: pre-training does work.
Many people in the industry worry that doing heavy pre-training and adding lots of general data might actually be harmful — that it could hurt model performance. What we see with Astra is that it's at least a bonus, at least not a bad thing. We should stay the course with confidence.
Finally, the only real difference between us and Anthropic or OpenAI might be that they're integrating this infra into general-purpose large models, while we're building specialized, dedicated models.
The reality is, a general-purpose language model cannot run inference on a robot at a reasonable speed or be deployed there. You genuinely need a dedicated embodied model to do this — it's simply the more efficient approach.
👦🏻 Koji (Crossing)
Poke Robotics recently released a video of a "robot making mapo tofu." Huazhe, in your view, could Astra accomplish a task like that? More fundamentally — does a robot completing a specific task prove that its underlying model has truly gotten stronger? If not, what metrics should we be looking at?
🤵🏻♂️ Huazhe Xu (Poke Robotics)
Astra is genuinely stunning. We tested it internally the very day it became available.
Huazhe Xu | Founder, Poke Robotics; Assistant Professor, Institute for Interdisciplinary Information Sciences, Tsinghua University
If you think of embodied tasks as requiring semantic generalization plus spatial generalization plus physical generalization, Astra is relatively weak only on the physical side — it's relatively strong on semantics and space.
We gave Astra a prompt, and it recognized everything on the table, regardless of category — it always moved toward the right place. With previous VLM or large models, the robot would basically get there, start flailing around, and that was the end of it.
But one unique thing about Astra is that it can actually grasp objects — and grasp very hard-to-grasp things. For example, a chopstick lying flat on a table: for a robot, picking up a small object like that usually requires pressing it against the table edge, or even letting it slide, before it can grab it. Astra can now pick it up.
At that point in our testing, we wondered: maybe rotation is its weakness? So we tried having it stand the chopstick upright and insert it into a cup. Surprisingly, it could do that too. So it's not just 2D space — its performance across the entire 3D space is quite good. But when we asked it to do complex tasks involving physical contact — like using chopsticks to pry something apart — it fell short.
I think this is the last stronghold of embodied robotics companies: understanding physical change.
We also tried using Astra for the kinds of tasks embodied AI companies love to test — stacking boxes, folding clothes — and found that Astra couldn't do any of them. And among all extremely complex tasks, making mapo tofu is certainly one of the hardest.
Back to Astra: what it can do today is still relatively limited to embodied tasks in the spatial-semantic realm. On complex contact-rich tasks, the only things it managed were inserting a chopstick into a cup, and handover — picking up an object, passing it to the other hand, and placing it on the other side. We ran that many times and succeeded once or twice.
Astra inspired a thought similar to what Professor Mengdi Wang (Director of the Center for AI Innovation at Princeton University) discussed in her keynote earlier: embodied models should also be connected into Codex, or into a harness environment.
Because embodied models work in general-purpose scenarios, but the harness needs strong semantic capability — the stronger the harness's semantic capability, the more intelligently the embodied model can be used.
Take grasping fruit. When people first train models, they start with foam fruit. But that data is actually very harmful: with foam fruit, you can just apply more force and pinch it up. You can never grab a real fruit that way. So we want the model to take a look first: if it's foam, use the original grasp; if it's a real fruit — say, a pineapple — find a way to grab the green leaves on top instead of gripping the body.
Most embodied models don't have this recognition ability. We need the model to first tell the robot — via CoT (chain-of-thought) — whether this is a real pineapple or a fake one, and then grasp accordingly.
So I believe the end state should be a complete system connecting the large model, the embodied model, and the physical world together.
👦🏻 Koji (Crossing)
Yujun, in your view, are the capabilities Astra is now demonstrating a signal of some kind of scaling law for embodied AI today?
👮🏻♂️ Yujun Shen (Ant Lingbo Technology)
My view is similar to Huazhe's, maybe a bit more radical. I believe embodied AI will gradually influence the development path of large models and cloud-based models.
First, the way an embodied model ultimately works must be deployment on a robot — which is different from the "turn-based conversation" mode of digital-world models.
In the digital world, you ask it a question and it answers — and while it's answering, you can't keep probing. The interaction is linear. But a robot's work depends on continuous input from its onboard sensors, and that input never stops — even while the robot is mid-operation, new input keeps streaming in, and the robot needs to adjust its reasoning at any moment based on it.
I believe embodied models may ultimately become a tool used by higher-order models.
As a tool, it needs its own training paradigm, because it has to handle scenarios with a constant stream of input while continuously outputting policy.
Why do I say embodied scenarios might open up new development directions for higher-order, interactive expert-type models?
Here's an example: conversation between people is actually multimodal — not just language and vision, but many external factors too. Say I'm chatting with someone and it suddenly starts raining outside. Seeing the rain might change my mood and how I talk. Or if I notice the person looks unwell, I might hold back much of what I was about to say and immediately switch to something else.
Today's cloud-based digital-world models haven't considered this, because they don't need to yet — their interactions happen behind a screen, conducted purely through vision and language.
But in the future, if robots really converse with people, the amount of information they can take in will be enormous, and much of it will come from real-world sensors. We'll observe the weather, sense the temperature... and all of that will shape the model's output.
In the future, as robots gradually enter daily life and bring more data about the physical world and real life, this data will become new training corpus for large language model companies, which can use it to become smarter.
Robots will no longer be cold intelligences hiding behind a screen, but agents that can sense their surroundings like humans do and adjust the way they converse with people as conditions change.
👦🏻 Koji (Crossing)
All three of you were generally quite optimistic just now, seeing mostly opportunities and inspiration. Anything to add, Zheng?
👨🏻💻 Zheng Han (Sudu Tech)
Actually, this is getting closer and closer to a point I've been making for a long time: the upper and lower layers will be separated. The upper layer of abstract understanding will be stratified.
I've been saying this for years: Facebook AI Research (FAIR)'s biggest competitor is actually OpenAI, and recently Anthropic as well. Another Robotics researcher from DeepMind also just joined Anthropic.
One more point: the foundation of robotics is skills. The generalization ability and high success rate of low-level skills must match the level of the upper-layer model. You can't have a low success rate with only some generalization — that's a fatal problem when the upper and lower layers connect.
So when embodied-AI companies integrate with upper-layer models, they have to pay attention to this: generalization under a high success rate.
At the end of last year, we did a demo with the Qwen model doing language interaction. It understood the surrounding environment and objects, and ultimately broke things down into reasoning-generated operation steps. But it absolutely depended on extremely reliable, stable low-level manipulation of the environment and objects to complete the training for the entire action sequence.
This idea has been brought back to the forefront this year, and I think it's a major trend — especially after Astra appeared.
The Battle Over Scenarios:
What Metric Proves Embodied AI Has Crossed the Bubble?
👦🏻 Koji (Crossing) There are some real-world doubts about the embodied-AI industry right now, mostly around commercialization: lots of demos, hot fundraising, but where is the scenario that can actually be replicated at scale and keep customers paying over time?
This next question goes to the three CEOs of embodied-AI companies. If you could only look at one metric, which one best proves that embodied AI has moved past the bubble-stage doubts and truly entered the industrial phase?
👨🏻💻 Zheng Han (Sudu Tech)
The demands that research and commercialization place on robots are exactly the same as with industrial robots and automation before — a high success rate is the prerequisite for the vast majority of tasks.
In commercial scenarios, the vast majority of tasks require a robot success rate close to 100%. Only a very small number of tasks can tolerate an 80% success rate or allow a second attempt at correction.
Under this premise, our difference from automation equipment is this: we still need a degree of generalization across objects and environments, and we can't make up for it with massive amounts of post-training. Otherwise, every new scenario would require heavy overfitting, and that would defeat the whole point of embodied AI.
So when it comes to commercialization, our biggest test is first of all algorithmic: maintaining generalization under a high success rate. Of course, the challenges that follow — hardware reliability, how to build the service layer — can't be avoided either.
💂♂️ Qian Wang (Independent Variable Robotics)
If I had to name one metric, it's this: customers paying sustainably — paying for cutting-edge technology.
That's the ultimate criterion, and also the most realistic one.
A lot of today's commercialization isn't actually a partnership where customers pay sustainably. It might be a specific form of cooperation for a specific historical moment. Or it might follow the playbook of the previous era — traditional automation, the last generation of robots.
But everyone should really think about this: what is this generation of robots actually better at than the last one? What real value can it deliver to customers?
This is already starting to happen. Recently, in a logistics scenario, we genuinely accomplished things that traditional robots couldn't do, and we exceeded human-level ROI. The things that can truly be deployed and continuously generate productivity — those matter most.
On the other hand, a company has to make money. With money, you can build bigger models and keep exploring the frontier of AI.
Language model companies went through a similar path. At first they made no money at all, but once they reached a stage where they were genuinely useful, they began actively commercializing. Commercialization and frontier advancement reinforce each other.
In a sense, commercializing too early is harmful. But we've probably passed that phase — we're now entering the stage where a flywheel effect kicks in and the two drive each other.
🤵🏻♂️ Huazhe Xu (Poke Robotics)
There are several types of embodied-AI commercialization.
One is the post-training type: I partner with a certain brand or a certain factory and build a closed loop inside it. Say I set up a small oden food stall outside my home — the core metric is how many hours I need to stably deploy this, and how many stalls I can open. This follows the same deployment logic as traditional robotics — it's all about efficiency and ROI conversion.
Second, I think another commercialization metric for this wave of embodied AI resembles the path of large language models. In the short term, there may be no visible economic return, but it will be a "step-change" commercialization path.
Why does everyone subjectively feel that large language models are so useful?
Because the cost of error is different. If GPT outputs an answer with a 50% success rate, I just chat with it a few more rounds and I'll very likely get a good result. But if a robot completes a task with a 50% success rate, that means there's a 50% chance it smashes a cup — and everyone will think it's useless.
Even so, we still have to unwaveringly pursue the "foundation model-ization" of embodied AI, because that current 50% success rate is 50% across all tasks. We need to wait until it climbs from 50% to 60%, 70%, all the way to 99.9% — that's when commercialization becomes the real commercialization of this wave of embodied AI.
That's also what we're truly looking forward to: the moment the foundation model reaches a certain stage and starts eating huge chunks of the physical world.
Looking Back from Five Years Out:
What's Overrated, What's Underrated?
👦🏻 Koji (Crossing) Last question. There's a saying: people always overestimate how much technology will change in the next two years, but underestimate how much it will change in the next ten. If you look back at this moment from five years in the future, what do you think is being underestimated in embodied AI right now? And what's being overestimated?
👨🏻💻 Zheng Han (Sudu Tech)
I think the most overestimated thing is: the sophistication of China's supply chain.
There are indeed a lot of options, but there's still some work to do before the supply chain that embodied AI needs today can actually meet the maturity level required for our real-world iteration.
First, we need some volume to support it. Second, many of the sensors and key components in the supply chain are scattered across mature industries — like the automotive supply chain or the industrial robot supply chain. In practice, when it comes to embodied AI, the current supply chain is still some distance from large-scale industrial manufacturing standards, though it's definitely a solvable problem.
On the underestimated side — responding to what Huazhe just said about reaching a 99.9% success rate — it may take a long time, but people don't need to be too pessimistic about the difficulty.
I think that within the next one to two years, everyone will see robots able to handle entire major categories of tasks across many industries.
Of course, if you mean robots being able to do 99.9% of all tasks, that would indeed take a very long time.
👮🏻♂️ Shen Yujun (Ant Lingbo Technology)
Embodied AI is a complex systems-engineering problem. People may still be underestimating the capability of the system as a whole, tying many questions — whether it can be deployed, the cost of solving problems — to model performance. But that's not actually the case.
Because robot commercialization ultimately comes down to cost, the robustness of the whole system, and the business model, among other things. The model is just one link in the chain.
Take deployment, for example. Merchants definitely look at cost: do I really need this particular robot? Do I need the complete robot? Could I get by with just the dual arms?
As for what's overestimated — right now we're somewhat overestimating "model-training technique."
I've also heard voices saying that embodied AI is about to be disrupted by digital-world models — that if you just stockpile a batch of physical-world data and train it the old way, you can produce an embodied model. That doesn't hold up in my view.
Embodied AI may follow the same pattern as the digital world, but it definitely won't follow the same technical route. Because the final application scenario determines that the model will be different. The digital world is conversational, but embodied AI must involve the robot reasoning while it works.
Embodied AI will certainly have its own new training paradigm. That paradigm can support continuous processing of physical-world information — possibly 24/7, even 365 days a year, nonstop, around the clock.
💂♂️ Qian Wang (Independent Variable Robotics)
Looking back five years from now, I think people will feel that we still underestimated the importance and potential of embodiment.
Although today we've already recognized that embodiment matters — that it's a critical component of AGI — I don't think people have truly understood it yet.
To follow up on Astra's question: why does data matter?
Because it really does contain certain kinds of intelligence that can't be obtained any other way. Things like complex physical interactions, all kinds of physical processes, and as Professor Shen mentioned, sensor noise and the inherently uncontrollable nature of the physical world — none of this can be captured through video or 3D, let alone code.
I used to study physics, and I found that a huge share of innovation and ideas come from so-called physical intuition. Of course there's another path: logical reasoning, the kind of deep search capability that math provides.
Throughout the history of human scientific research, we've found that these two things can't substitute for each other. For certain problems, mathematical thinking is faster; for others, physical thinking is faster.
So to build genuine AGI, there's no way around this part. You can train it into the same model, or train separate models in a layered architecture. But the bigger issue is that this capability genuinely has to come from the real world, or from simulation, or some other channel, and then be injected into the AI system.
At the application level, people are also underestimating the importance of embodiment for ROI.
Recently, whether in Silicon Valley or back home in China, there's been enormous FOMO around RSI — both the hype and the fear.
My view is that with current language model capabilities, full RSI simply isn't achievable. Because it's missing the most critical link: physical re-manufacturing (self-replication in the physical world), which language models can't touch.
Also, a language model can modify its own training methods and many parts of its training pipeline, but fundamentally, we still need to scale up — more compute, more chips, more electricity — and language models can't do any of that either.
That's why in the United States right now, data center construction has become a major bottleneck. You still need people to work with rebar and concrete; you still need people to tune the parameters on semiconductor fab lines.
But five years from now, I believe people will realize that embodied AI can do these things in the not-too-distant future. That's the day true RSI arrives.
Right now, the digital world is moving far faster than the physical world.
I often joke that if Anthropic laid off all its employees today and used agents to develop its next-generation model, progress would definitely slow — human taste still matters a lot — but would that mean they couldn't develop the next model at all? I don't think so. They definitely could. But if you removed all the people from a semiconductor fab and left it entirely to AI, that absolutely wouldn't work.
Also, building an app today no longer requires the huge teams, long timelines, and heavy coordination of five years ago — like spending a year to ship an app. Today, one person with enough quota can spin up a bunch of agents and build it in a few hours.
Building an airplane, on the other hand, still takes maybe 1,000 people, a massive supply chain, and many factories. Maybe five years from now, with the help of embodied AI and general-purpose language models, building an airplane could be as simple as building an app is today.
By then, the entire production process could be closed-loop, and the human economy would reach the day when silicon-based truly breaks free from carbon-based.
Perhaps someday, we'll still need to chart a distinctly Chinese path for AI development — and embodiment could be a very important starting point, or a very important part of it. Maybe every company will end up training its own language model, too. Who knows.
🤵🏻♂️ Huazhe Xu (Poke Robotics)
What's overhyped, quite obviously, is the race for data volume.
These days, some people claim to have a million hours of data, others claim several million hours, and still others say so-and-so has already bought up this much data, and if you don't buy in, you'll fall behind.
I've also seen models on the market trained on truly enormous volumes of data, and they haven't turned out to exceed expectations — or to be any better than models trained on tens of thousands of hours. Blindly chasing volume for its own sake is seriously overhyped.
What's underestimated, I think, is the overall progress of intelligence models — the progress of embodied AI models.
When people talk about embodied AI solving general-purpose problems, they say it might take five or ten years. I think within three years, embodied AI will start serving many real-world scenarios — general-purpose service, not the kind that's been post-trained for a specific task.
👦🏻 Koji (Crossing)
Everyone has painted a future that's genuinely exciting to look forward to. Just as Qian Wang mentioned — will building airplanes one day become as simple as building apps?
Thank you to our four guests, and thank you to everyone in the audience for your time. See you all at next year's Bund Summit!