Trace Intelligence Secures Over 100 Million Yuan in Funding: Fudan PhD Aims to Customize Inference Chips for Diverse Edge Scenarios | Yunqi Partners
Moving from method validation to commercial delivery
As AI moves from the cloud onto more real-world devices, on-device inference is running into an increasingly concrete problem: requirements for model capability, power consumption, die area, and cost vary enormously across scenarios, and a single general-purpose chip can hardly cover them all.
Recently, Yunqi Capital portfolio company Trace Intelligence, a chip design company focused on on-device AI, closed a new round of funding exceeding 100 million yuan. Following this round, the company will further advance the definition, design, and tape-out of its first 6nm dedicated inference chip.
Yunqi Capital's investment perspective:
We remain bullish on the new compute demand created by AI's accelerating penetration into edge devices and the physical world, and on the innovations in chip design and delivery models that this trend will spawn.
Dr. Hongyang Pan has spent years working deeply in EDA, moving from research to tool-building entrepreneurship and now to chip products, and he has thought long and hard about how AI can genuinely reshape the chip design process. At the same time, the team is rapidly building out the engineering capabilities required for real tape-outs and mass production. We look forward to seeing Trace bring truly AI-native methods into commercial chip delivery, and explore a new chip design paradigm for the era of on-device AI.
The following is excerpted from DeepTech
Physical AI and on-device inference were the two keywords Hongyang Pan thought about most when he founded Trace Intelligence. In 2025, while still a PhD student, Pan founded an AI EDA company, Fuxin Zhigan, attempting to turn his research on physics-aware logic synthesis into a commercial product that would shorten chip design iteration cycles. He began to realize that AI might change not just the middle and back-end stages of chip design, but the entire way chips are defined and designed.
He believes AI models in a given domain typically go through three stages: in the first stage, the model architecture hasn't yet converged, and training engineers are still exploring the optimal structure; in the second stage, the architecture has largely converged, and iteration happens mainly at the parameter level; in the third stage, model capability has matured, large models are distilled into small ones, and the focus shifts to low-cost deployment.
Over the past two years, more and more AI hardware startups have emerged, with wearables, AIoT, and security as typical scenarios. This also means a considerable share of AI models have already entered the second and third stages. General-purpose, flexible GPUs and NPUs are better suited to first-stage models; for the latter two stages, Pan believes, the real answer is customer-centric custom AI chips that push PPA to the extreme. Such chips can maximize on-device AI capability, help more customers actually ship AI applications, and thereby push the entire on-device inference market forward.
That is Trace Intelligence's vision.
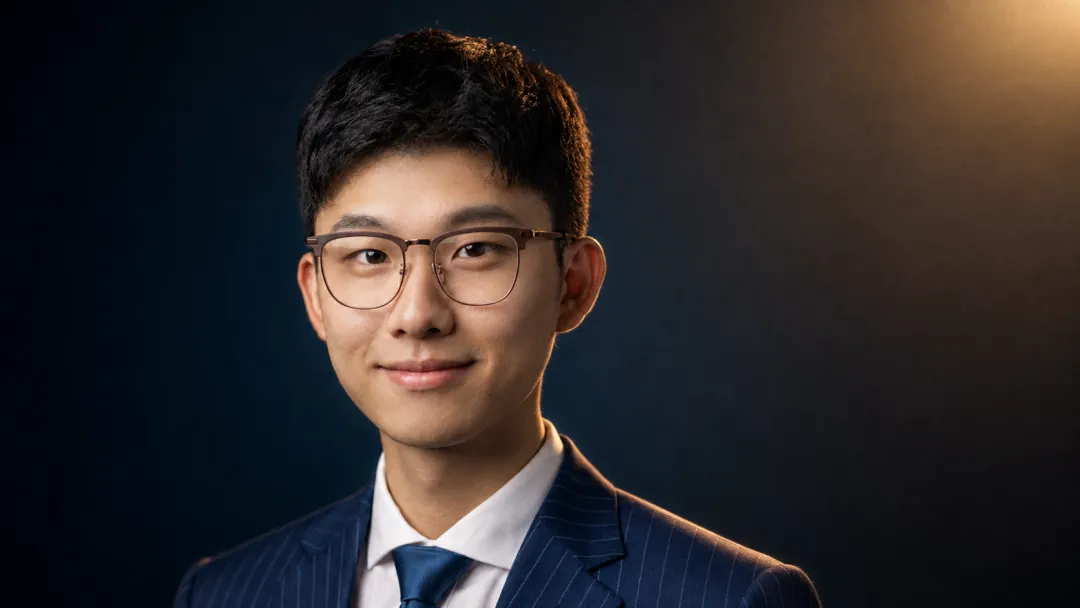
Photo: Trace Intelligence founder and CEO Hongyang Pan (Source: interviewee)
Around this goal, Trace Intelligence has assembled an inference chip team combining international AI chip R&D experience with design automation capabilities. The co-founder and CTO was an early team member and principal engineer at SambaNova, with chip design and mass-production experience spanning dataflow architectures, GPUs, and edge NPUs, along with both software and hardware development skills. Co-founder Keren Zhu, a professor at Fudan University, previously interned at Cerebras and NVIDIA Research, accumulating research and engineering experience in AI-assisted chip design.
Around the core founding team, the company has brought together talent across SoC design, verification, back-end implementation, compilers, and supply chain, forming a professional division of labor covering model understanding, chip architecture, hardware-software co-design, and engineering implementation — jointly advancing the development and delivery of dedicated on-device inference chips.
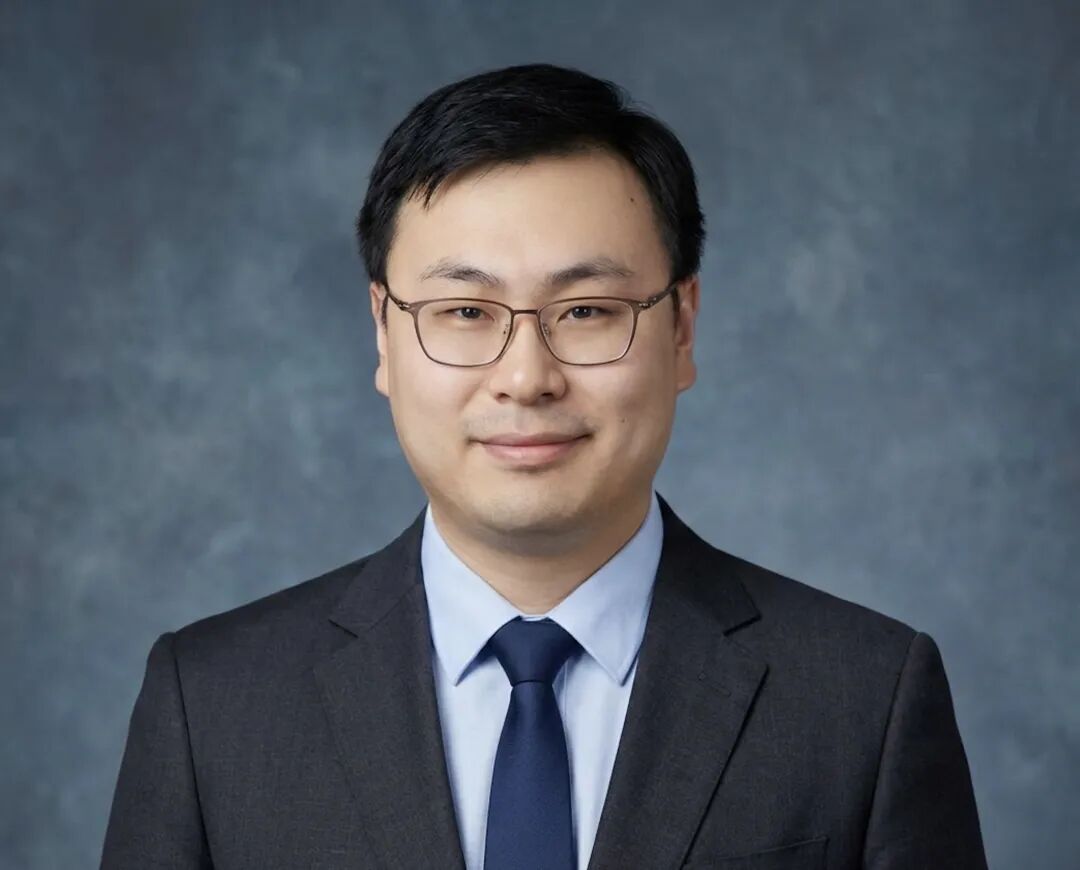
Photo: Trace Intelligence co-founder and Fudan University professor Keren Zhu (Source: interviewee)
On design methodology, Trace has built an AI-native chip design flow that starts from customer requirements, co-optimizes the software stack and hardware architecture, and uses AI to drive design, verification, and physical implementation. This approach aims to reduce the development cost of custom chips and shorten iteration cycles, making chip customization viable for the broad and fragmented on-device inference market.
Trace is currently transitioning from method validation to commercial delivery. The team previously completed an academic tape-out of a 28nm RISC-V out-of-order core, running through the full design flow from specification to layout. On the commercial side, the company is conducting model evaluation and joint product definition with multiple AI hardware and consumer electronics customers, with the first focus on on-device speech recognition.
On funding: following an incubation round a few months ago, Trace Intelligence recently closed a new round exceeding 100 million yuan. The round was led by a top-tier fund with participation from Yunqi Capital, and existing shareholders Monolith and the Fudan Science and Technology Fund continued to follow on. After this round, the company's most important task in the next phase is to work with customers to complete the definition, design, and tape-out of a 6nm dedicated inference chip.
Around the plans for its first commercial chip, we spoke with Trace Intelligence founder and CEO Hongyang Pan.
Below is the full conversation between DeepTech and Hongyang Pan.
Why does on-device AI inference
need custom chips?
DeepTech:
Why did you choose the on-device AI inference market? Isn't it already very crowded?
Hongyang Pan:
The on-device inference market is enormous. When people talk about on-device AI, the first things that come to mind are usually phones, AI PCs, and cars. These markets ship huge volumes and already have fairly mature chip solutions.
But beyond these markets, there are many needs that aren't well served — smart wearables, security, AIoT, and Embodied Artificial Intelligence, for example. The tasks these products run tend to be more concentrated, and their requirements for die area, power consumption, cost, and model capability differ enormously. Traditional AI inference chips therefore struggle to meet all these needs.
Take smart wearables: why haven't most people developed the habit of using one or two smart wearable products long-term? The reality is that many products today still don't deliver a good enough experience. Constrained by area and power, the chips often can't run larger models offline, so tasks have to be sent to the cloud. Cloud round-trips introduce latency and are subject to network conditions, making it hard to convince consumers to pay for extra AI capabilities. Local offline processing is especially important in scenarios like real-time speech processing and real-time translation.
Trace's answer is to build highly customized, radically simplified chip architectures around the customer's model and scenario, pushing PPA close to its physical limits.
DeepTech:
The idea of customizing chips for customers isn't new. Why hasn't it become mainstream in the past?
Hongyang Pan:
I think there are several reasons.
First, whether customers are willing to give up flexibility depends on which stage the model has reached. The three stages I mentioned are essentially a process of gradually trading flexibility for better PPA and cost-effectiveness. When the architecture is still changing rapidly, customers need sufficiently flexible chips; customization only truly pays off once the architecture has converged, iteration happens mainly at the parameter level, or the model has been distilled small enough. And only in the past two years have enough scenarios reached the latter two stages.
Second, the structure of mainstream edge markets naturally favors general-purpose solutions. Today's highest-volume edge scenarios, like AI PCs and phones, are themselves multi-functional hub devices that require highly flexible chips; at the same time, their chip demand is so large that a chip company can generate substantial revenue by winning just one of these markets. On top of that, chip design and manufacturing costs are extremely high — traditional chip companies typically need teams of several hundred people and two to three years from design to mass production — so the rational choice is naturally to build one product that covers as many customers as possible, rather than optimizing to the extreme for one customer or one category.
Third, the chip industry sits close to the downstream, so the ups and downs of upstream applications transmit directly into the chip market. Over the past few years, the cloud has been the relatively higher-margin domain. Companies like OpenAI, Anthropic, Meta, Amazon, Microsoft, and Google have continuously invested massive capital expenditure, so the trend toward customized chips appeared in the cloud first — Etched and Taalas are typical examples, and Google and Meta are both developing more customized chips in-house. Conversely, many on-device inference scenarios have failed to take off because suitable chip solutions didn't exist; and because the applications didn't take off, chipmakers became even less willing to develop chips specifically for those scenarios. What Trace aims to do is break this cycle.
Trace's methodology
From customer requirements to a chip
DeepTech:
You keep mentioning "defining chips around customer requirements." What does that actually mean in engineering terms?
Hongyang Pan:
Customers in different scenarios and applications have different chip requirements, but they generally revolve around a few dimensions: area, power consumption, performance, cost, and the maximum model size the chip can support. These dimensions aren't orthogonal to each other. We have a mature methodology that finds the optimal chip specification based on the customer's requirements across these dimensions.
At the architecture and design level, the problems to solve include the memory bandwidth wall, power consumption, thermal constraints, ultra-low latency, and software stack redundancy. There are many available approaches, such as customized dataflow architectures, hardened weights, and hardened operators.
This methodology includes various modeling tools and Agentic EDA, capable of completing the entire flow from architecture definition to chip design in a very short time, and even handling design tasks for multiple customers concurrently. The direct result is a dramatic reduction in design cost: defining and designing a chip traditionally takes 200 to 300 people and about two years. Our goal is to compress that to 50 people and three to six months.
DeepTech:
How do the customers you're currently engaging with typically work with you?
Hongyang Pan:
We're a customer-requirements-centric company. The customers we engage fall roughly into two categories: one already has clear model and product requirements with fairly specific demands; the other can't find a suitable chip on the market and wants us to find the largest model that can run within the PPA constraints they give us.
We also co-develop algorithms and co-define chips with customers. For example, if a customer has extreme low-power requirements, always-on functions can run on our self-developed ultra-low-power NPU, while functions that don't need to be always-on sit in other compute units that get powered down when idle. In short, we work with customers to find the most suitable solution.
DeepTech:
Chips are a very expensive undertaking. Customization means redoing the work each time. How does Trace solve the cost problem?
Hongyang Pan:
Cost can be divided into two parts: expenses in the chip design phase, and expenses in the chip manufacturing phase.
In the design phase, on the front end we have a complete toolchain that automatically analyzes the customer's model and PPA requirements and outputs the compute, bandwidth, and area budgets allocated to each hardened operator; the instantiation and verification of each hardened operator can also be highly automated. On the back end, we have an Agentic EDA platform covering everything from design specification to layout, which compresses design cycles and labor costs. At the same time, we don't just want to cut headcount and timelines — we also want to increase our ability to handle projects concurrently. As the flow matures, the same system can support chip designs for multiple customers in parallel.
One major fixed expense in the manufacturing phase is the photo mask, which is analogous to the printing plate in a printing process — the larger the chip volume, the more easily mask costs get amortized. Trace's entry point is mask reuse. Many on-device model architectures are essentially stable; customers simply keep training on the same model to improve capability and launch the next product generation. When the model architecture stays the same and only the parameters change, a re-tape-out only requires modifying the few mask layers corresponding to the ROM. This kind of iteration might take only two or three weeks of design time, mask costs could drop to a tenth of the first tape-out, and re-manufacturing, chip return, and testing could be compressed to about two months. If only the contents of off-chip DRAM change, parameters can simply be updated via OTA. Only architecture-level updates or process node migrations require a full mask set redo. So a customer's second tape-out with us costs significantly less than the first.
That's the cost of the chip itself; the other side is the cost of using the chip. A chip usually comes with a complex software layer, including the compiler, operators, frameworks, firmware, and runtime. Because our approach hardens the model architecture and some parameters, software stack complexity drops dramatically. What the customer receives is closer to out-of-the-box, and their additional investment in software stack development and maintenance shrinks as well.
As an AI-native design house
what role does AI play?
DeepTech:
You've mentioned that the company is an AI-native design house. Can you elaborate on the role AI plays in it?
Hongyang Pan:
We've thought about this a lot. Our CTO previously spent two years at a well-known American AI chip unicorn, during which he worked alongside two core members of OpenAI's Jalapeño project.
Our judgment is that AI chip design requires a methodology distinct from traditional chip design, with the core principle that scenario, software, and hardware must be co-designed. The concept of "hardware-software co-design" has been around for a long time, but in real design flows, software and hardware remain relatively decoupled stages. When OpenAI designed Jalapeño, it truly broke down that barrier. It made two counterintuitive design choices: not separating PD (Prefill/Decode), and using L1 cache instead of a scratchpad. The former factored the fluctuations of real-world workloads into the chip design upfront; the latter moved what was originally a software optimization problem into hardware design. Relying on AI, modeling, and internal tools, OpenAI produced a chip with a near-optimal architecture in nine months, catching up to Vera Rubin in a single product generation.
Trace likewise has an innovative methodology and AI tools. Unlike OpenAI, we take the path of extreme specialization bound to customer requirements, but the essence is the same: at the architecture definition stage, you must fully understand the customer's requirements and scenario; and hardening the model architecture means bringing software difficulty into hardware design. So we too need a methodology that connects the top-level scenario all the way down to low-level hardware design.
Within this methodology, AI plays a very important role. In the customer engagement stage, AI combined with our self-developed modeling automatically analyzes the customer's model and constraints and returns the optimal PPA plan. In the stage from design specification to RTL, an AI-driven compiler automatically generates RTL along with the corresponding verification environment and test cases, completing verification self-checks. In the stage from RTL to layout, we already have a relatively mature Agentic EDA platform that dramatically shortens the design cycle. The entire flow connects every step from user requirements to layout, gradually transforming engineers from executors of each step into the people who set the goals, constraints, and boundaries for the whole chip. Invocation, execution, verification, and feedback between design stages are controlled by AI as much as possible, with humans contributing knowledge and judgment within the flow.
We also have a clear plan to keep feeding the experience accumulated in chip design — and even manufacturing experience gained from working with foundries — back into this flow, driving coordination from architecture design through the back end and into manufacturing.
As this AI design flow matures further, it can also support handling design requirements from multiple customers in parallel. Our core idea is to use AI to raise the production efficiency of the entire chip design organization.
DeepTech:
Specifically in chip engineering, what is AI best at? And worst at?
Hongyang Pan:
We've always maintained an open but cautious attitude toward using AI. Chip design demands strong determinism with essentially zero tolerance for error, so the first thing to guarantee is correctness.
At this stage, AI is mainly used to replace tedious, repetitive work, to conduct large-scale design space exploration, and to drive result convergence. Critical junctures still require verification by senior engineers to ensure quality. Humans play two main roles in this process: first, constraint-setters who help AI explore in a targeted way; second, quality inspectors who accept or reject AI-processed results.
DeepTech:
You previously completed a real tape-out of a 28nm RISC-V chip. What practical capabilities did that chip validate? And where does the work stand now?
Hongyang Pan:
Building on the open-source RISC-V ecosystem, we went from design specification to layout in about four months, then spent two more months on optimization and convergence, ultimately producing a 28nm RISC-V out-of-order core running at 1 GHz, with good results on area and performance benchmarks.
It validated two more fundamental things: first, the team has genuinely walked through the complete flow from specification, RTL, synthesis, physical implementation, and signoff to tape-out and chip testing; second, design flaws exposed during chip testing — such as voltage instability — demonstrate that many constraints and judgments in chip design cannot be obtained solely from papers, benchmarks, or simulation. They must be accumulated through real silicon feedback.
This led us to a clear conviction: to do AI-native chip design, the order must be to first possess real tape-out capability, then gradually encode that experience into agents — not to build an agent first and assume it can naturally produce chips.
As of now, the inference chip's architecture and RTL have taken shape, and the system can repeatedly explore design options. We plan to tape out our first chip in early 2027. The Agentic EDA platform has also improved significantly: we've integrated our past accumulation in EDA point tools, design iteration, and physical implementation, and in 2026 we added multi-agent scheduling and closed-loop control. On RISC-V designs, the flow can now run with near-zero human intervention.
Trace's moat
and advantages
DeepTech:
EDA companies like Synopsys and Cadence are now building their own agents; traditional design houses have more real tape-out and mass-production experience; and general-purpose chipmakers already have strong delivery capabilities. Looking at these three types of players together, what is truly unique to Trace?
Hongyang Pan:
What I believe is unique to Trace is an innovative chip design methodology and full design flow that combines customer requirements and scenarios while connecting software and hardware. As I mentioned, the edge market is highly fragmented: some scenarios need extreme optimization of chip area and power, others need to support larger, smarter models. Opening up this enormous market requires deeper collaboration with customers to jointly customize more innovative chip architectures.
The companies you mentioned can be divided into three categories.
The first is AI EDA and general-purpose model companies. They only deliver tools; they don't engage with top-level customers and don't directly deliver actual chips.
The second is traditional design service companies. "Traditional" in two senses: first, traditional in process — the entire design flow is led primarily by human engineers. Second, their experience comes mostly from chips with traditional architectures. Design service companies mostly provide services around RTL, synthesis, and PPA optimization. But the kind of highly customized chip design Trace does needs to cover customer requirements, scenarios, and large models and algorithms. The overall design thinking and risk profile are completely different from traditional chips — much of the difficulty and risk hasn't disappeared, it's just shifted into the chip design stage. For example, if a single computation in a large model isn't hardened correctly, the chip is a dead piece of silicon. Traditional design services simply don't consider these things.
The third is general-purpose chip design companies. As I described earlier, they target different markets than we do.
DeepTech:
Your first commercial chip hasn't come back yet. Could "AI-native" be, for now, just an organizational aspiration?
Hongyang Pan:
The first commercial chip is still in development, but AI usage has already penetrated every stage of our chip design. Beyond the Agentic EDA platform, we have a suite of AI-empowered tools covering model analysis, architecture specification definition, RTL generation, and verification automation.
OpenAI's Jalapeño has actually already proven that AI-native isn't just an aspiration. That said, Jalapeño is a relatively general-purpose AI inference chip. What it proves is that an AI-empowered methodology and design flow can let a company without chip design DNA find the optimal architecture and design in a very short time, catching up in a single product generation to Vera Rubin, which NVIDIA developed specifically for agent scenarios. What Trace aims to prove in the dedicated inference chip domain is something else: given known customer requirements and scenarios, can our methodology efficiently design a chip that matches those requirements and pushes PPA to the extreme?
We believe that under Trace's business model, as our engagement and collaboration with customers deepens, we'll form a relationship of mutual growth. For customers, we'll understand their needs better and help them improve product competitiveness. And as we design more and more chips, that experience will feed back into our AI design flow, strengthening its robustness and efficiency.
DeepTech:
After completing this funding round, what's the most important goal for the next phase? Does the company already have definite customers — are you at the stage of designing chips together with customers?
Hongyang Pan:
The most important goal for the next phase is to define and deliver a real chip together with customers. We've already engaged with multiple AI hardware and consumer electronics customers and are currently mainly at the model evaluation and joint product definition stage, with relatively clear cooperation intentions formed with some of them.
Our first commercial chip corresponds to real customer requirements from the very beginning of its definition, rather than building a chip detached from any specific scenario and then looking for customers. Next, we'll work with customers to determine the first chip's concrete specifications based on their models, product form factors, power, and cost requirements.
On the tape-out path, we'll first do an MPW (multi-project wafer) run on a 6nm process with a customer-endorsed model, then proceed to full-mask tape-out and bring-up. This isn't another benchmark — it's completing Trace's first commercial chip end to end.
This will be expensive, so we need to both run the complete design and tape-out process and build out capabilities in SoC mass production, back-end signoff, hardware-software co-design, and production ramp-up. After this funding, the biggest investment will go to tape-out and manufacturing, followed by the team, EDA licenses, compute, and supply chain partnerships.
DeepTech:
If you look back a few years from now, what concrete results would prove that today's technical route and business judgment were right?
Hongyang Pan:
Looking back a few years from now, I think the most important thing would be validating whether our current judgment about the relationship between model evolution and compute form factors holds.
We believe a model entering a concrete application roughly goes through three stages: in the first stage, the architecture still iterates frequently, requiring general-purpose processors like GPUs and NPUs; in the second stage, the model architecture is stable while parameters keep updating; in the third stage, model capability has matured, and smaller distilled models enable low-cost deployment.
The further along you go, the lower the value of generality and the higher the demands on power, performance, area, and cost — making dedicated chips increasingly suitable.
Trace targets precisely the second and third stages. What we see first today are wearables like smart glasses and earbuds; in the future this will expand to scenarios like Embodied Artificial Intelligence. Robots in particular need large numbers of models running locally for real-time perception, decision-making, and control — local inference is already a clear requirement.
As AI moves from model innovation to industrial deployment, a portion of compute will inevitably shift from general-purpose to extreme customization around stable models and specific scenarios. What Trace wants to do is turn these converged models into chips, fast.
DeepTech:
One last, longer-range question. If you look ten years ahead, what do you hope AI inference will look like then?
Hongyang Pan:
The true sign that AI has become ubiquitous isn't how big the models are — it's that ordinary people no longer need to think about where it runs, whether it needs a network connection, or whether their data is being recorded. To achieve that, compute must be close enough to people, and cheap enough.
Looking far ahead, the form I imagine is one where edge and cloud truly work together. Every task automatically lands in the most appropriate place: the part closest to the user, most privacy-sensitive, and most latency-sensitive gets done on the edge device; the part needing broader knowledge and longer context goes to the cloud. The judgment and switching in between is completely invisible to the user.
The edge chip's role is as the gateway to this system — it decides what stays local and what goes up to the cloud. The better it does its job, the better the whole system's cost, latency, and privacy boundaries become.